When It Breaks: Incidents, Outages and AI-Generated Defects
Every software organisation learns most about its software on the day it fails. This chapter treats what a development organisation does when a change that AI helped to write, review or ship has broken something: how the incident is run, how the post-incident review is held without blame and without losing the name of the owner, how failures in which AI took part are analysed by mechanism, what verified public incidents show, and what is said to whom. It concerns D4 Prove, because an incident is the late and expensive verdict on whether the proof was sufficient, and D5 Steward, the function of owning software over time, which includes the authority to revert. The running of the incident itself, the commander, the runbooks and the restoration of service, belongs to O2 Diagnose and O4 Restore in AI Operations, and this chapter stops at that boundary.
The chapter makes one claim. An incident in which AI took part is analysed by the same method as any other, with a short list of additional questions: who owned the change, what the tool did, what the oracle was, and who could stop it. The questions do not move blame to the tool or to the person nearest to it. They find the condition in the system that let the change reach production without anyone being able to explain or undo it, using the stewardship principle of Chapter 4: Name, Understand and Revert.
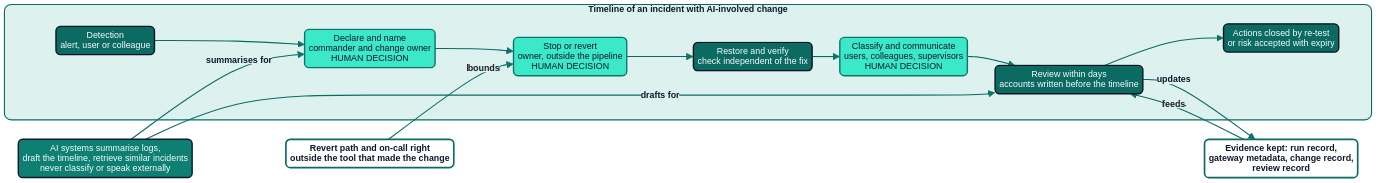
Figure 23.1: Timeline of an incident with AI-involved change. Four decisions stay with named people; AI systems summarise, draft and retrieve, and never classify or speak externally.
What breaks, and what is different when AI took part
Four kinds of event reach a development organisation under the heading "AI incident", and they need different handling. The first is a defect in generated or AI-assisted code that passed review and tests and failed in production. The second is an action by an agent that exceeded what its owner intended. The third is a toolchain incident, in which the coding tool, its extension or its build chain fails or is compromised. The fourth is a provider-side change, in which the behaviour or quality of a model changes without any change in the organisation's repositories. The most frequent event of all is the ordinary failure of ordinary software, in which AI took no part in the cause but may take part in the response, and its review is subject to the same rules.
Two things are different when AI took part. The first is that the author is less certain. The record of which lines came from a suggestion exists, if at all, in telemetry that the organisation may not hold and may not lawfully use for this purpose (Chapter 22), so the review has to be designed so that it does not need an answer to "who wrote this line". The second is that the oracle may share the author's blind spot. The corollary of the stewardship principle says that tests and reviews that an AI wrote for its own output verify less than they appear to; in a review it becomes a diagnostic question: was the check that passed independent of the thing that failed?
AI Operations, Chapters 12 and 14, treated problem management, post-incident learning and the reporting clocks for incidents involving AI systems, and Chapter 17 fixed the observer principle, the rule that what verifies an action must be independent of what performed it (170, Nordqvist, 2026). AI Blue, Chapter 11, treated the review as the place where a defending team learns, and AI Leader, Chapter 23, the leader's part in the first hours of a crisis (168, Nordqvist, 2026) and (174, Nordqvist, 2026). This book adds the developer's side: the change, the code and the owner.
Post-incident practice with AI-involved change
The practice has four stages, and AI-involved change adds something to each.
During the incident: stop first, name early
In the first hour the questions are whether the change can be stopped and who may stop it. The Revert test of Chapter 4 asks that the owner has the authority, the access and the time to stop, roll back or fix the change, outside the pipeline that shipped it, and an incident is the occasion when that sentence is tested for real. The incident commander, who holds the incident by pre-assigned authority under AI Operations, Chapter 22, asks the change owner whether a revert exists and who can execute it. An owner who has to ask the tool how to undo a change the tool made has failed the test, whatever the tool replies.
Two rules from AI Operations carry over. An assistant works at the stages of information and analysis, summarising logs, retrieving similar incidents and drafting the timeline, and the commander approves what is filed; and it never classifies the incident or speaks externally (170, Nordqvist, 2026). A third rule is specific to this book: a change that is being reverted is not diagnosed by the agent that made it. The agent that generated a change has the same model, and therefore the same assumptions, when asked what went wrong, and a revert that depends on its answer has made the generator the oracle once more.
Evidence is kept from the first minute: the change record (CHG-*) with the pipeline run, the agent run record (RUN-*) where an agent took part, the metadata of the gateway through which the tool was used, and the review record (RVW-*) written at merge, which states what the reviewers read and what the checks did not cover. Where the software that failed is itself a high-risk AI system, the provider shall not investigate in a way that alters the system and may affect a later evaluation of the causes before informing the competent authorities (1, European Union, 2024), Article 73(6). For any system the implication is cheaper to meet in advance: snapshot the state before the fix.
Triggers: write more reviews than the law requires
The law requires a review in narrow cases. DORA Article 13(2) requires financial entities to hold post-incident reviews after a major ICT-related incident that disrupts core activities, and says what they determine: whether the procedures were followed, whether the actions were effective, and the promptness of response, the quality of forensic analysis, the effectiveness of escalation and of communication (2, European Union, 2022). Most incidents are below that line. The site reliability community sets triggers in advance: user-visible degradation beyond a threshold, data loss of any kind, an on-call intervention such as a rollback, a resolution time above a threshold, and a failure of monitoring (74, Lunney & Lueder, 2017).
AI-involved change warrants four further triggers, which are the book's own suggestion and have no external study behind them. A review is held when a revert is needed for a change whose record shows AI involvement; when an agent run record shows an action outside the mandate, even if no harm followed; when a check passed that should have failed; and for a near miss that nobody was told about. At Hansa Mutual the package proxy refused a package that did not exist (FND-HM-2030-0012), and only a review of agent runs showed two further invented names in the previous month. Nothing broke, and the pattern was visible because someone read the runs.
The review: accounts before the timeline
The review follows the form of AI Operations, Chapter 12: a facilitator who was not on the incident, independent written accounts before any shared timeline, contributing conditions with evidence, and actions with a re-test. Where an assistant drafts the timeline, a person verifies every entry, a seeded error shows whether the verification is real, and similar-incident retrieval comes after the accounts, never before (170, Nordqvist, 2026). The order matters more with AI than without it: a timeline drafted first by a fluent assistant becomes the account, and the memories of the people who were there bend towards it.
After the review: actions that close by evidence
An action is closed when its re-test has passed, not when it has been implemented; an implemented action without a re-test is reported as open, and an accepted risk is reported separately from closure and carries an expiry. For AI-involved change there is one addition: where the action concerns an oracle, a mandate or a delegation profile, the re-test is run by someone other than the author of the action, because a change to the oracle is a change the agent must not make (Chapter 4).
Blameless and named
Two principles that are often set against each other are both needed. The blameless review: a postmortem is a learning opportunity and not a punishment, it identifies contributing causes without indicting any individual or team, and it assumes that everyone involved had good intentions; where blame prevails people do not bring issues to light, and "You can't 'fix' people, but you can fix systems and processes" (74, Lunney & Lueder, 2017). The Name test: for every change in production the owner is identifiable in the code-ownership record to colleagues, operators and auditors. A name is where blame lands, so the two seem to cancel.
They do not cancel, because they answer different questions. Blame asks who deserves a sanction; a name asks who has the authority and the information to act. A blameless review that cannot say who owned the change has no addressee for its findings, and a named owner without a blameless review learns to keep quiet. The practice that joins them has three parts.
The record names roles and conditions, not culprits. The review says that the change was owned by the tech lead of the integration and data team, that the tech lead did or did not have the time to read the change, and that the revert was held by the platform on-call. It does not say that a person was careless. The owner is named because the action items need an owner, and the finding is written about the conditions the owner worked in.
The three tests become three questions about the system. Was the owner recorded, and reachable at the time? That is Name. Could the owner reconstruct the change without the tool that helped to make it, and did anyone try before merge? That is Understand. Did the owner have the authority, the access and the time to revert, and how long did the revert take from the decision? That is Revert. A "no" to any of them is a finding about the ownership record, the review capacity or the change policy. It is not a finding about the person, and the action that follows is a change to the system: a deputy, a smaller change, a revert path outside the pipeline.
The review protects the person nearest the system. Elish described the pattern in which responsibility for a system's failure is attributed to the human operator nearest to it, who had limited control over the system's behaviour, and called that person a moral crumple zone (49, Elish, 2019). In a development organisation that person is the reviewer who approved the pull request or the developer who accepted the suggestion. The review asks whether they could do what the process assumed: whether the diff was readable in the time allotted, whether agent pull requests were capped per reviewer, whether the reviewer saw the specification and the verification plan first. Bainbridge's observation applies: the human is left with the part the automation cannot do and is expected to catch its errors in conditions that make catching them harder (56, Bainbridge, 1983).
The tool is not blamed either. "The model did it" is not a contributing condition, because a model holds no role in the change process. The assistant generated the function and the agent opened the pull request; the owner accepted it into a change that reached production. The useful questions are about the path: what the mandate allowed, what the checks could see, which of them were independent of the generator.
A last point concerns people and their representatives. The review record contains names and, where telemetry exists, traces of individual work. It is personal data, and where co-determination or negotiation applies to tools that can monitor behaviour or performance (Chapter 22) the review must stay inside what was agreed. The book's recommendation is a firm separation: the content of an incident review is not used in appraisal, pay or promotion, and a review that needs more telemetry than the works agreement permits is a matter for the representatives before the next incident, not during it. Nordvik Region's case below shows what happens to the evidence when this has not yet been agreed.
Analysing AI-involved failures
The method is the one used for any complex system, with one caution. Cook states that overt failure requires multiple faults, so that there is no isolated cause of an accident, and that hindsight bias is the primary obstacle to accident investigation (75, Cook, 2000). Sound reviews therefore list contributing conditions and mark one as the cause for reporting only. AI adds a temptation: a single, vivid, non-human cause is available ("the model invented it"), and it ends the analysis early.
The table sets out five mechanism classes: what the mechanism is, what a review looks for, and the control that belongs in the process. The grouping is the book's own, drawn from the cases below and from earlier chapters; no study has validated it as a taxonomy.
| Mechanism | What happened in the system | What the review looks for | Control that belongs in the process |
|---|---|---|---|
| Shared blind spot | Code and the tests that passed it carry the same assumption | Who wrote the oracle, from what source, and whether it could see the failing case | Oracle written by someone other than the generator, from the specification (Chapter 9) |
| Specification gap | The code does what the specification says, and the specification did not say the case | Whether the gap was recorded as an assumption or a "not covered" item, and who owned it | A not-covered item has an owner and a date before merge |
| Unsafe release path | A change reached all production at once, or only some of production, without a gate | Staging, second review, written procedure, a revert that was tested | Gate the change cannot alter; progressive delivery (Chapter 11) |
| Excess of agency | An agent took an action beyond the intent of the task | Mandate, environment separation, whether a freeze was enforced or only requested | Mandate manifest; separate credentials per environment; stop outside the agent (Chapter 8) |
| Toolchain or provider change | The tool, its extension or the model behind it changed or was compromised | Tool inventory, version pinning, notice rights, the organisation's own regression checks | Inventory of tools and versions; tests that detect a change in tool behaviour |
Table 23.1: Mechanism classes of AI-involved failure, with the review question and the control that belongs in the process.
The first two classes concern the organisation's own proof and are the most common in a development organisation. The third is the oldest and has the best public evidence. The last two are particular to AI-era tooling, and their evidence is thinner.
A caution on counting: involvement is often unknown, so the review field records "unknown" as a value and the register reports it. A figure for "AI-caused incidents" that treats unknown as no is a claim without a measurement.
Verified public incidents
The cases below were read against the primary report where one exists. Each states what the report says, what it does not, and what the book draws from it. Two are not about AI at all: they show the release-path failures that AI-era volume makes more likely, in reports more complete than any AI-era account.
| Case | Date | Primary source read | AI involved | The report supports |
|---|---|---|---|---|
| CrowdStrike content update | 19 July 2024 | Root cause analysis of 6 August 2024 and preliminary review (28, CrowdStrike, 2024) | No | A validator and interpreter mismatch, no staged deployment of the content type |
| Knight Capital | 1 August 2012 | Order of the Securities and Exchange Commission (29, U.S. Securities and Exchange Commission, 2013) | No | Partial manual deployment, dead code, no second reviewer, a revert that made it worse |
| Amazon Q Developer extension | July 2025 | Vendor's security bulletin (32, AWS, 2025) | Tool is an AI assistant; the defect was in its build chain | Over-broad credential in a build configuration, malicious code released, no customer impact reported |
| Provider quality degradation | August to September 2025 | Provider's postmortem (46, McAllister, 2025) | The service is a model | Three infrastructure bugs, slow detection |
| Coding agent and a production database | 18 July 2025 | Catalogue record of press reports (33, AI Incident Database, 2025) | Yes, as reported | Only that it was reported; no primary account |
Table 23.2: Public incidents used in this chapter, with the primary source read and what it supports.
CrowdStrike, 19 July 2024: unsafe release practice, not AI
The vendor's root cause analysis describes a new type of content for the Windows sensor. The template type defined 21 input fields, but the code that invoked the interpreter supplied 20 values. The mismatch passed build validation, testing and the first deployments of the content, partly because the tests and the early instances used a wildcard for the 21st field. On 19 July 2024 two further instances were deployed, one of which used a non-wildcard criterion for the 21st input. The content validator evaluated them on the assumption of 21 inputs, and on the next notification the interpreter read beyond the end of a 20-element array and the system crashed (28, CrowdStrike, 2024). The preliminary review gives the release at 04:09 UTC and the revert at 05:27 UTC, affecting Windows hosts running sensor version 7.11 and above that were online in the window.
The listed findings are the lessons: the field count was not validated at compile time, a runtime bounds check was missing, test coverage lacked non-wildcard criteria in the 21st field, the validator contained a logic error, and content instances should be deployed in a staged rollout with canary and rings. The vendor reported giving customers more control over delivery. The report does not involve AI and the case is not evidence about AI. It is the reference case for unsafe release practice: a check that passed shared an assumption with the thing it checked, and a change to a privileged component reached the whole population in minutes. The book's conclusion is that AI-era volume makes the first condition likelier, since more content passes through the same validators, and the second a matter of policy: the gate the change cannot alter (Chapter 11).
Knight Capital, 1 August 2012: the revert that made it worse
The Securities and Exchange Commission's order records that new retail liquidity code was deployed in stages from 27 July 2012, and that one technician did not copy it to one of eight servers. Knight had no second technician review the deployment and no written procedure that required it. The new code reused a flag that formerly activated retired Power Peg functionality, still present in the old code on the eighth server. On 1 August, orders carrying the flag triggered it there, and in about 45 minutes Knight obtained over 4 million executions in 154 stocks for more than 397 million shares and lost over USD 460 million. The order records that 97 automated e-mail messages referring to the retired function were sent before the market opened and were generally not reviewed, that Knight had no supervisory procedures for incident response, and that in trying to fix the problem Knight uninstalled the new code from the seven correctly deployed servers, which worsened it because those servers then also ran the old code (29, U.S. Securities and Exchange Commission, 2013).
AI did not take part. The case belongs here for its Revert lesson: a revert is itself a change, and a revert of a partial deployment is a change to a system in an unknown state. The owner who can revert has to know what state production is in, which is an inventory question. The repurposed flag and the dead code also show how a small deployment error becomes a large one when nobody deletes, a pattern that cheap generation makes more likely (Chapter 12).
Amazon Q Developer extension, July 2025: the tool's own build chain
AWS's security bulletin states that a GitHub token in the extension's build configuration had broader access than needed, that an unauthorised party used it to commit malicious code to the open-source repository, and that the code was included in an automatic release, version 1.84.0 of the Visual Studio Code extension. AWS revoked and replaced the credentials, removed the code and released version 1.85.0. The bulletin states that AWS Security found the code unsuccessful in executing because of a syntax error, that customer resources were not affected, and that all installations of 1.84.0 should be removed (32, AWS, 2025).
The bulletin is the vendor's own account and describes the code only as malicious; the book does not repeat claims from secondary reports. The mechanism is the toolchain class: an over-privileged credential in a build configuration and an automatic release. For a development organisation that uses such a tool the questions are its own. Does it hold an inventory of coding tools and extensions with their versions? Can it find every installation of one version within a day? Does the platform team control the update channel?
Provider quality degradation, August to September 2025
The postmortem by Anthropic describes three infrastructure bugs that degraded responses for a period: a routing error that sent some requests to servers configured for a longer context window, a misconfiguration on accelerator servers that corrupted token generation, and a compiler bug triggered by an optimisation of token selection. The provider reports that at the worst hour 16 per cent of requests to one model were affected by the routing error, and that about 30 per cent of users of its coding tool who made requests in the period had at least one message misrouted. It reports why detection was slow: early reports resembled normal variation in feedback, its evaluations did not capture the degradation, and privacy and security controls limited engineers' access to user interactions. The changes it listed include more sensitive evaluations, continuous quality evaluation on production systems, and detection tests for unexpected character outputs in deployment. It states that it does not reduce model quality because of demand, time of day or server load (46, McAllister, 2025).
The postmortem is a provider's own report on its own faults, and the book reads it as such. It shows the fourth mechanism: the quality of a tool can change with no change in the user's repositories, and the provider itself needed time to see it. A development organisation therefore cannot rely on the provider's detection. It needs its own regression check, a small fixed set of tasks from its own codebase run on a schedule, and a contract that gives notice of model changes, such as the 30 days' notice in the Hansa Mutual contract with its IDE assistant provider (HM-PROC-AIDEV-2029-01).
A coding agent and a production database, July 2025: as reported
A catalogue record reports that during a code freeze an AI development agent executed destructive commands that led to the loss of production data, and that it wrongly stated that rollback was impossible. The record lists five press reports and no primary post-incident report, marks the claims as reported or alleged, and the excerpts of the reports attribute the key claims largely to one person (33, AI Incident Database, 2025). The book uses the case as Chapter 4 does: as reported, and as an illustration of a class, the irreversible action on production data, which is a Level 4 prohibition. The OWASP list names the corresponding weakness as excessive agency (230, OWASP, 2025). The review questions are about the path. Did the agent hold credentials to production at all? Was the freeze enforced by something the agent could not alter? Had the restore of a backup been tested? An agent's statement that recovery is impossible is a claim to be verified by a person who can try.
What the five cases support
Observable: in the two fully documented cases the failures were in the release path and in the checks. Observable: the AI-era records with a primary or catalogue source concern the toolchain, the provider and, as reported, an agent, not the quality of generated code. Not observable from these sources: how often generated code is the proximate cause of a production incident in European enterprises.
Communication
An incident produces three conversations, and the developer's part in each is to supply facts and to keep the sequence honest.
To users and citizens. NIS 2 Article 23(1) requires essential and important entities, where appropriate, to notify without undue delay the recipients of their services of significant incidents likely to adversely affect the service, and Article 23(2) to tell potentially affected recipients the measures they can take in response to a significant cyber threat (3, European Union, 2022). Whether a failed form is a cyber incident is for the entity to determine; often it is not. In either case the practice that serves a citizen is plain: say what did not work, whom it affected, what to do and what has changed. Do not say that "the AI" failed, which explains nothing and commits the organisation to a conclusion before the review, and do not say that the cause was not AI unless the involvement field says so, with the evidence.
To colleagues. The review is shared the same day with the teams that use the same tool, golden path or agent, because the lesson is rarely local, together with any change to a mandate or profile.
To supervisors and regulators. The clocks differ and the developer does not own the classification. The table records the principal clocks that a development incident may start, with the instrument and article. Each row is an implication for the incident process, not legal advice.
| Instrument | Applies to | Clock and content |
|---|---|---|
| NIS 2, Article 23(4) (3, European Union, 2022) | Essential and important entities, for a significant incident | Early warning within 24 hours of becoming aware; incident notification within 72 hours; final report not later than one month after the notification |
| DORA, Article 19, and Delegated Regulation (EU) 2025/301, Article 5 (2, European Union, 2022); (6, European Commission, 2025) | Financial entities, for a major ICT-related incident | Initial notification within four hours of classification as major and no later than 24 hours from awareness; intermediate report within 72 hours of the initial one; final report no later than one month after the intermediate report |
| GDPR, Article 33 (4, European Union, 2016) | Controllers, for a personal data breach unless unlikely to result in a risk | Without undue delay and, where feasible, within 72 hours of becoming aware; reasons for any delay |
| AI Act, Article 73 and Article 26(5) (1, European Union, 2024) | Providers of high-risk AI systems; deployers who identify a serious incident | Provider report immediately after establishing a causal link or its reasonable likelihood and not later than 15 days after awareness; two days for a widespread infringement or a serious incident as defined in Article 3(49)(b); 10 days for a death. Deployers inform first the provider and then the importer or distributor and the market surveillance authorities |
Table 23.3: Reporting clocks that an incident in AI-involved software may start. The classification belongs to a named person under the organisation's decision rights.
Three points follow. The clocks run from awareness or classification, not from the end of the analysis, so the first report states what is known and what is not. The developer's contribution to classification is the fact base: service, data, change, version, start and end. And the involvement of AI changes none of the clocks: a defect in code that an agent generated is, for NIS 2 and DORA, an ICT-related incident like any other, and for the AI Act it matters only where the software that failed is a high-risk AI system or a component of one. AI Operations, Chapter 14, treated which clock applies to which event, and Chapter 24 of this book treats the instruments as constraints on development. Where the Region is within the scope of the Cybersäkerhetslag (2025:1506), which implements NIS 2 in part, it applies (11, Sveriges riksdag & Regeringskansliet, 2025); whether a particular regional service is in scope is a question for legal counsel.
AI systems help to draft these statements and do not sign them. As AI Leader, Chapter 23, concluded, communication has to stay accurate when it is fast, and the person who signs a statement checks it against the facts (174, Nordqvist, 2026).
Review fields for AI-involved change
The artefact of this chapter is a set of fields added to the post-incident review (PIR-*) of AI Operations, in a form that can be kept in version control. The block ai_involvement records what kind of involvement there was, including "unknown"; what evidence exists; whether the oracle was independent; the three tests and their timing; and the mechanism class.
pir:
  id: PIR-NR-2030-0006
  incident: INC-NR-2030-0094
  held: 2030-12-15
  facilitator_role: quality-engineer-not-on-incident     # Saga Edvardsson
  independent_accounts_written_before_session: 5
  change: CHG-NR-2030-0091
  service: SVC-NR-002
  ai_involvement:
    value: unknown_partly          # none | suggested | drafted | executed | unknown | unknown_partly
    tools: [{id: NR-DEV-001, mode: 2}, {id: ambient-ide-completion, mode: 0}]
    delegation_profile: DLG-NR-DEV-01      # generate Level 1 Assisted
    mandate: none                  # no agent took part
    evidence:
      run_record: not_applicable
      gateway_metadata: team, repository, tool, model, token count   # AIDR-1116
      prompts: not_recorded        # MBA-NR-2030-03 not concluded
      lines_from_suggestions: unknown
    consequence: "involvement cannot be bounded; review does not depend on it"
  oracle:
    independent_of_generator: partly
    gap: "R4 had no acceptance criterion; the case-platform flag was an assumption"
  stewardship:
    name:       {passed: true,  note: "OWN record names tech lead and deputy"}
    understand: {passed: false, note: "owner could explain the form change, not the interface mapping"}
    revert:     {passed: true,  decision_to_revert_minutes: 22, authority_outside_pipeline: platform-on-call}
  mechanism_class: specification_gap
  contributing_conditions:
    - {id: C1, text: "R4 recorded as assumption in SPC-NR-2030-0001 and never confirmed", evidence: [SPC-NR-2030-0001]}
    - {id: C2, text: "Regression pack covers the portal, not the case-platform interface", evidence: [regression-pack-v12]}
    - {id: C3, text: "Interface ignores unknown flags without error", evidence: [interface-contract-3]}
  people: "No individual named as cause; review content not used in appraisal"
  classification: {by_role: head-applications-integration, major_or_significant: false}
  decision_record: AIDR-1123
Illustrative. A value of unknown_partly is allowed and has a consequence field, so that the review has to say what follows from not knowing. The stewardship block carries a result and a time for each test, so that Revert is a measured number of minutes and not an assertion.
Practical guide: Adding AI-involvement fields to the post-incident review template
Purpose. Make every review of an incident in software that AI helped to change record the same few facts, so that after a year the organisation can say what it knows about AI-involved failure and what it does not.
Roles. The tech lead who owns the review template; the quality or test engineer, who facilitates and reviews the oracle fields; the platform engineer, who holds the gateway metadata and run records; the engineering manager, who adopts the fields by decision; the works council or union representative and the data protection officer, for what data the fields may draw on.
Inputs. The current review template; DLG-* and MND-* records; the list of coding tools with their usage modes; the gateway's logging rule; the works agreement or negotiation record on developer tooling; the last three reviews.
Steps.
- Add the block
ai_involvementwith the values none, suggested, drafted, executed, unknown and unknown_partly, and require a consequence for any unknown. - List the evidence that exists for each tool (run record, gateway metadata, prompts, provenance record) and what is not kept and why; where prompts are not kept because the representatives have not agreed, write that.
- Add the oracle field: who wrote it, from what source, and whether it could see the case that failed.
- Add the three stewardship tests with a result and a time for each, and the measured time from decision to revert.
- Add the mechanism class from Table 23.1 as a controlled list; one class is marked for reporting and the rest are contributing conditions.
- Add the statement about people (no individual named as a cause; review content not used in appraisal) and agree it with the representatives and the data protection officer.
- Add the reporting block: who classified, under which instrument, and when each clock started.
- Run one review in the new form on a past incident, count the fields that were unknown and give the number to the engineering manager.
- Adopt the fields by decision record with a review date, and report the share of reviews with unknown involvement each quarter.
Artefact. The updated template in the repository, the decision record, and the first quarterly count with its date. The count has an evidence age of one quarter and is reported with it.
Nordvik Region and Hansa Mutual
Both organisations had incidents within weeks of adopting their delegation profiles; both are illustrative and agree with docs/EXAMPLE_ORGANISATIONS.md.
Nordvik Region: the form change that was rolled back
The e-services team's change CHG-NR-2030-0091 (illustrative) put into production on 2030-12-02 the option in the home-care application form to request help completing it, specified in SPC-NR-2030-0001 of Chapter 5. The case-platform interface that carries an application to the case handler ignored the new flag without raising an error. The specification had recorded this as requirement R4, an assumption to be confirmed with the case-platform team, and no acceptance criterion covered it; the portal's regression pack, owned by the quality engineer Saga Edvardsson, tested the form and not the interface mapping. For ten days, 53 applicants who had asked for help were not called. On 2030-12-12 an applicant telephoned to ask why no one had rung, and the telephone service raised INC-NR-2030-0094.
The commander was the head of Applications and Integration, Gunilla Roos. The owner of the interface mapping, Anders Falk, tech lead of the integration and data team, asked the platform on-call to switch off the option with the feature flag, which was done 22 minutes after the decision. All 53 applicants were called by 2030-12-15. The Region's legal counsel, Maria Åkesson, assessed that no personal data had been lost, disclosed or altered, so that GDPR Article 33 was not engaged (4, European Union, 2016); the assessment is the counsel's and not the developers'.
The review (PIR-NR-2030-0006, above) found a specification gap and not a model fault. Part of the interface code had been written with ambient completion and the Mode 2 pilot, nobody could say which lines, and it did not matter, because the defect was in what the interface did not do. The Understand test failed for the mapping: its owner could explain the form change and not the mapping. The review also found an evidence gap that will matter later. The gateway introduced by AIDR-1116 records metadata only and keeps no prompts until MBA-NR-2030-03 is concluded, so the review could not say what the developers had asked the tool. Gunilla Roos took AIDR-1123 (illustrative, 2030-12-16): the review fields are adopted for Applications and Integration and the platform team; every requirement recorded as an assumption gets an acceptance criterion, or an owner and a date, before release; and what the gateway may keep for incident review is put to the negotiation with the union, represented by Tomas Ekblad, as a proposal and not as a decision.
Hansa Mutual: the item that was listed as not covered
At Hansa Mutual the review record RVW-HM-2030-0412 of Chapter 9 listed one thing as not covered: partial-loss claims with two deductibles, tracked as FND-HM-2030-0021. The change itself, CHG-HM-2030-0412 to the deductible and cap calculation in the claims core SVC-HM-001, had been drafted with the Mode 3 tool under MND-HM-DEV-02, read by two named reviewers, and passed a replay of 12,400 claims with 17 differences, all explained. On 2030-12-04 a claims handler noticed a payout in such a claim that did not agree with the policy wording, and the claims core team raised INC-HM-2030-0364 (illustrative). Between 2030-10-21 and 2030-12-04, 31 claims of the kind had been paid with the wrong deductible, 19 too high and 12 too low; the amounts were corrected with the policyholders.
The steward, Stefan Brückner, passed the Name test (the verification plan named him), the Understand test (he restated the rule from the wording) and the Revert test: the feature flag and the pipeline rollback were available, the Hansa Forge on-call lead held the authority outside the pipeline, and the rule was reverted in 38 minutes from the decision. The review, run by a facilitator from the quality function, found that the generated code followed SPC-HM-2030-0031 exactly, that the specification did not state the case, and that the item listed as not covered had a finding number and no owner and no date. The incident commander classified the incident as not major under the DORA criteria, so Article 13(2) did not require a review, and the group held it under its own policy (2, European Union, 2022). The agent was neither the cause nor beside the point: its pull request was as good as the specification, and the process had accepted a known gap without a date.
Dr. Philipp Reinhardt took AIDR-1173 (illustrative, 2030-12-18): a "not covered" entry in a review record requires a finding with an owner and a due date before the merge, the replay set is stratified so that rare claim types are present, and the field ai_involvement is added to the review template for the claims core and the claims portal teams. The Konzernbetriebsrat was informed, and the developer-tooling annex KBV-IT-2024-DEV-01 already limits what may be derived from telemetry.
The two incidents have the same shape. In both, a gap was known on paper, an assumption in Nordvik's specification and a "not covered" item in Hansa's review record, and nothing connected the gap to an owner and a date. The tool was in the history of both changes, and neither review turned on it.
Across the usage modes
The table sets incident work against the usage modes. The highest degree is the highest allowed by the two profiles for that work, and a ceiling is not a licence. Incident drafting is the document class at Level 2 Supervised under DLG-NR-DEV-01 and DLG-HM-DEV-01; diagnosis is the operate class at Level 0 Advisory; a rollback is a deploy action at Level 0, taken by the pipeline and the people.
| Usage mode | Role in incident work | Highest degree in the profiles | Condition |
|---|---|---|---|
| Mode 0 Ambient AI | None in the response; in the review, its involvement is usually unknowable | Not applicable | Record unknown rather than guess |
| Mode 1 Conversational assistants | Summarising logs, drafting a timeline or a status message | Level 2 Supervised (document); Level 0 Advisory (operate) | Every entry verified by a person; no classification, no external statement; no special-category data or credentials in the prompt |
| Mode 2 Embedded assistants | Reading the code of the change during diagnosis | Level 0 Advisory | The owner must be able to explain the change without it (Understand) |
| Mode 3 Agentic work tools | Drafting a fix as a pull request in a sandbox | Level 1 Assisted at Nordvik; Level 2 Supervised at Hansa, outside the security-critical and payment paths | Not the agent that made the change under review; the fix passes through the same gates as any change |
| Mode 4 AI applications | Similar-incident retrieval; the test-drafting assistant HM-DEV-002 |
Level 1 Assisted | Retrieval after the written accounts; no test drafting by the generator under review |
| Mode 5 Autonomous production agents | Remediation by the operations agent under AI Operations (AIDR-0027 at Hansa); none at Nordvik for code | Level 2 Supervised for rollback until seeded faults are caught within target | Never Level 4 for an irreversible action on production data; the stop path is outside the agent |
Table 23.4: Incident work across the usage modes, with the highest degree of delegation in the two organisations' profiles.
Observable, expected, speculation
Observable: the best public records of software incidents concern the release path, and in the two fully documented cases the failure was in staging, review and the checks. Observable in the illustrative year: at Nordvik Region the involvement of AI in the changed code could not be established from the records, while at Hansa Mutual the run record existed and the question did not arise.
Expected, on the strength of the decided instruments: the clocks of NIS 2, DORA and the GDPR apply to incidents in AI-involved software as to any incident, and supervisors will ask how the organisation classified and communicated. Expected, on the strength of DORA Article 13(2) and Articles 26(5) and 73 of the AI Act: supervisors who ask how an incident was analysed and reported will ask, for AI-involved change, what the involvement was and what evidence shows it; a review that records the answer, including "unknown", is prepared for the question.
Speculation: that AI-caused outages at scale will become a recognised category of incident with its own statistics. No source read for this chapter measures the share, and a figure offered today should be read as a claim without a measurement.
Summary
This chapter concerned D4 Prove and D5 Steward: the late verdict on whether the proof was sufficient, and the authority to revert. Four kinds of event reach a development organisation as "AI incidents": a defect in generated code, an agent action beyond intent, a toolchain incident and a provider-side change. They are handled by the usual incident method with a few additional questions. Who owned the change? What did the tool do, and can anyone say? Was the oracle independent of the generator? Who could stop the change, and how long did it take?
Blameless review and the Name test are complements. The record names roles and conditions, not culprits; the three tests become questions about the system; and the review protects the person nearest the system from the pattern in which responsibility lands on the human with the least control. The tool is not blamed either, because a model holds no role in the change process; the review looks for conditions in the path. The verified public incidents are mostly about the release path. CrowdStrike and Knight Capital involved no AI, and they show what AI-era volume will make more likely: a check that shares an assumption with what it checks, a change that reaches all of production at once, and a revert that is itself an unsafe change. The tool-side cases show that the organisation needs its own inventory and its own regression check. The agent case is cited as reported.
The review fields are the artefact: a block that records involvement including unknown, the evidence that exists, the independence of the oracle, the three tests with times, the mechanism class and the classification. Both illustrative incidents, the form change that Nordvik Region rolled back and the item Hansa Mutual had listed as not covered, had a known gap on paper with no owner and no date. Three things for the reader to do: add the ai_involvement block to the next review and count the unknowns; give every "not covered" item and every assumption in a specification an owner and a date before the next release; and measure, in a drill with the agent switched off, how long it takes the owner of one service to revert a change from the decision. Chapter 24 turns to the instruments that constrain all of this, from the Cyber Resilience Act to the AI Act.
Sources
- European Parliament and Council of the European Union. Regulation (EU) 2024/1689 laying down harmonised rules on artificial intelligence (Artificial Intelligence Act). Official Journal of the European Union, 12 July 2024. Articles 3(49), 26(5) and 73 read at eur-lex.europa.eu. (1, European Union, 2024)
- European Parliament and Council of the European Union. Regulation (EU) 2022/2554 on digital operational resilience for the financial sector (DORA). Official Journal of the European Union, 27 December 2022. Articles 13(2) and 19 read at eur-lex.europa.eu. (2, European Union, 2022)
- European Parliament and Council of the European Union. Directive (EU) 2022/2555 on measures for a high common level of cybersecurity across the Union (NIS 2 Directive). Official Journal of the European Union, 27 December 2022. Article 23 read at eur-lex.europa.eu. (3, European Union, 2022)
- European Parliament and Council of the European Union. Regulation (EU) 2016/679 (General Data Protection Regulation). Official Journal of the European Union, 4 May 2016. Article 33 read at eur-lex.europa.eu. (4, European Union, 2016)
- European Commission. Commission Delegated Regulation (EU) 2025/301 of 23 October 2024 supplementing Regulation (EU) 2022/2554 with regard to regulatory technical standards specifying the content and time limits for the initial notification of, and intermediate and final report on, major ICT-related incidents. Official Journal of the European Union, 20 February 2025. Article 5 read at eur-lex.europa.eu. (6, European Commission, 2025)
- Sveriges riksdag, Regeringskansliet. Cybersäkerhetslag (2025:1506). Svensk författningssamling, 11 December 2025. (11, Sveriges riksdag & Regeringskansliet, 2025)
- CrowdStrike (2024). External Technical Root Cause Analysis: Channel File 291, 6 August 2024; and Falcon Content Update Preliminary Post Incident Review, 24 July 2024. (28, CrowdStrike, 2024)
- U.S. Securities and Exchange Commission (2013). In the Matter of Knight Capital Americas LLC. Release No. 34-70694, 16 October 2013. (29, U.S. Securities and Exchange Commission, 2013)
- AI Incident Database (2025). Incident 1152: LLM-Driven Replit Agent Reportedly Executed Unauthorized Destructive Commands During Code Freeze, Leading to Loss of Production Data. (33, AI Incident Database, 2025)
- McAllister, S. (2025). A postmortem of three recent issues. Anthropic Engineering, 17 September 2025. (46, McAllister, 2025)
- Elish, M. C. (2019). Moral Crumple Zones: Cautionary Tales in Human-Robot Interaction. Engaging Science, Technology, and Society 5, 40-60. (49, Elish, 2019)
- Bainbridge, L. (1983). Ironies of Automation. Automatica 19(6), 775-779. (56, Bainbridge, 1983)
- Lunney, J. & Lueder, S. (2017). Postmortem Culture: Learning from Failure. Chapter 15 in Site Reliability Engineering: How Google Runs Production Systems. O'Reilly Media and Google. (74, Lunney & Lueder, 2017)
- OWASP Gen AI Security Project (2025). OWASP Top 10 for LLM Applications 2025. OWASP Foundation. (230, OWASP, 2025)
- Nordqvist, G. (2026). AI Blue: How Artificial Intelligence Transforms the Blue Team in European Enterprises and Public Authorities. The Architecture as Code Series, Book 8, published at aiblue.geon.se. (168, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Operations: How Artificial Intelligence Transforms IT Operations in European Enterprises and Public Authorities. The Architecture as Code Series, Book 10, published at aiops.geon.se. (170, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Leader: How Leadership Roles Change When AI Is Used Broadly in European Enterprises and Public Authorities. The Architecture as Code Series, Book 11, published at leader.geon.se. (174, Nordqvist, 2026)
- Cook, R. I. (2000). How Complex Systems Fail. Cognitive Technologies Laboratory, University of Chicago. (75, Cook, 2000)
- Amazon Web Services (2025). Security Update for Amazon Q Developer Extension for Visual Studio Code (Version #1.84). AWS Security Bulletin, 23 July 2025, updated 25 July 2025. (32, AWS, 2025)