Testers, Quality Engineers, Product Owners and Designers
Four roles sit on either side of the code: the product owner and the designer, who say what the software is for and how it should feel to use, and the tester and quality engineer, who find out whether it does what was said. When AI generates code cheaply, these four roles change more than most, and for the same reason: the cost of producing a change falls, while the cost of knowing what to build (D1 Frame) and of showing that what was built is right (D4 Prove) does not. This chapter describes how each role moves, where the boundary between them and the developer shifts, and what must not shift. It is for testers, quality engineers, product owners, designers, the developers and tech leads who work with them, and the engineering managers who draw their boundaries.
The chapter has one argument. The boundaries around intent and prototype are moving outwards, because anyone can now produce a running prototype. The boundaries around proof and ownership must not move: the oracle that decides whether a change is right stays independent of whatever generated the change, and a named person owns what reaches production. The role-boundary matrix at the end of the chapter is the artefact that makes the argument operational.
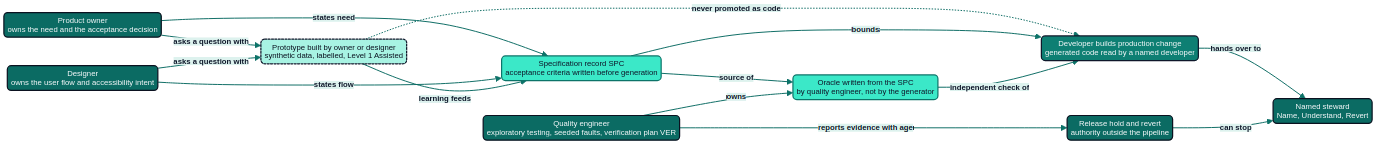
Figure 17.1: Role boundaries around frame, build and prove. Prototypes inform the specification and are not promoted as code; the oracle is written from the specification by the quality engineer; hold and revert authority sits outside the pipeline.
The chapter builds on the oracle and review material of Chapter 9, on the specification record of Chapter 5 and on the stewardship principle of Chapter 4: a named developer or team passes the tests Name, Understand and Revert, and the test oracle is independent of the generator. It takes over the independence principle of AI Purple, Chapter 15, that a loop closed by machines alone verifies nothing new (169, Nordqvist, 2026), the observer principle of AI Operations, Chapter 17, and its treatment of resilience as a claim with an evidence age in AI Operations, Chapter 19 (170, Nordqvist, 2026). It also uses the conclusions of AI Leader, Chapter 19, on leading specialists: write the first judgement before reading the draft, seed known errors, disclose AI use and protect the right to override (174, Nordqvist, 2026). Testing practice as such, and the testing of infrastructure as code, are treated in Architecture as Code (Chapter 13) (161, Nordqvist, 2025) and are not repeated.
Testers and quality engineers
The tester's role is the most exposed to a misunderstanding that sounds plausible: that a model which writes tests also removes the need for someone who owns testing. This section describes what the role did before, what AI adds, and what stays with a person.
What the role did before
A tester or quality engineer does four kinds of work. The first is designing tests from a specification: turning "a citizen can change address once per day" into cases, boundaries and expected results. The second is automating them, so that a regression pack runs on every change. The third is exploratory testing, in which a person learns the software while testing it and follows what looks wrong. The fourth is judgement about risk: which parts of the software deserve more testing, and when a release is not ready. In small organisations one person does all four. In large ones the work is split between test automation engineers, manual and exploratory testers and a quality lead.
Exploratory testing deserves a precise statement, because it is the part of the craft people assume AI replaces most readily and the evidence is thinner than either enthusiasts or sceptics suggest. A replicated experiment with 51 student subjects compared exploratory testing with test-case-based testing. It found no difference in defect-detection effectiveness, less design effort in the exploratory condition and more false-positive defect reports with test cases; the authors note that test cases have organisational benefits in managing and controlling testing in large organisations (203, Itkonen & Mäntylä, 2014). The population was students working in a laboratory, so the result is evidence that both approaches find defects and that they trade design effort against control, not evidence about professional testers on a production system. This book draws one conclusion from it: the two approaches complement each other, and an organisation that keeps only the one that a tool can draft has chosen on convenience.
What AI changes
AI changes the economics of the second kind of work. Drafting unit and integration tests, extending a regression pack and proposing test data are tasks that a coding assistant performs quickly. In the Hansa Mutual profile this is a licensed capability: the test-drafting assistant HM-DEV-002 drafts unit and integration tests for Java services at Level 1 Assisted. The question for the quality engineer is no longer whether tests can be produced at volume. It is which of those tests carry information.
A field report from industry shows the shape of the answer. At Meta, a system that generates mutants (deliberately introduced faults) and then asks a language model to write tests that catch them was applied to 10,795 Android Kotlin classes across seven software platforms. It generated 9,095 mutants and 571 privacy-hardening test cases, and engineers in test-a-thons accepted 73 per cent of the generated tests and judged 36 per cent to be privacy-relevant (195, Foster et al., 2025). Read with care: this is a preprint submitted to an industry track, a single organisation's deployment, and the abstract reports acceptance and relevance, not faults prevented in production. What it shows is a design in which the target of a generated test is defined by a fault and not by the code: the test exists to catch a stated defect. That is a different instrument from a test generated to describe what the code already does.
Whether faults of that kind are a fair stand-in for real faults has been studied. An analysis of 357 real faults in five open-source applications found a statistically significant correlation between a test suite's ability to detect mutants and its ability to detect real faults, independently of code coverage; 73 per cent of the real faults were coupled to mutants and 17 per cent were not (202, Just et al., 2014). Two conclusions follow for a quality engineer. A mutant score is a better indicator of a suite's strength than coverage alone, and it is not complete: a fifth of real faults in that sample were outside what mutants represent, which is where exploratory testing and domain knowledge remain necessary.
The role therefore shifts in weight. Less of the day goes to typing test code and more to deciding what must be checked, reviewing drafted tests for what they assert, maintaining the oracle and measuring whether the suite finds faults. The quality engineer becomes the owner of a verification plan (VER-*, Chapter 9) and not mainly the author of tests.
The independent oracle
A test oracle is the procedure that distinguishes correct from incorrect behaviour of the system under test. The survey that named the oracle problem observes that, without oracle automation, a human must determine whether observed behaviour is correct, and that when modelling, specifications, contract-driven development and metamorphic testing are not completely adequate, the final source of oracle information remains the human, who holds informal specifications, expectations and domain knowledge (178, Barr et al., 2015). Generating test inputs has long been easier to automate than judging results. Generative AI makes input generation cheaper still. It does not solve the oracle problem; it makes the oracle the scarce part.
The stewardship principle's corollary applies directly: the oracle must be independent of the generator. A test written by the same assistant, from the same code, in the same session as the change it checks tends to assert what the code does and not what it should do. The error is shared. There is also evidence that the shared error is systematic and not an occasional slip: a large-scale evaluation of over 350 language models found substantial correlation in their errors, and found that larger and more accurate models have highly correlated errors even with distinct architectures and providers (35, Kim et al., 2025). A second model checking a first model is a partial remedy at best, which is why the AI Purple independence principle prefers a check whose failure modes differ from those of the thing checked.
Independence has to be shown and not asserted. The practical test has four parts.
- Source. The oracle is written from the specification record (
SPC-*, Chapter 5) and from independent evidence such as archived production results, not from the code under test. - Author. The oracle for a change is written by someone other than the author of the change, and not by the generator that produced it. Hansa Mutual's delegation profile
DLG-HM-DEV-01states exactly this for test drafting, and Nordvik Region'sDLG-NR-DEV-01says an assistant is never the oracle for the same change. - Seeded faults. Known faults are injected and the suite is shown to catch them. The rate of seeded faults caught is a statement about the suite, and it is the measure AI Leader, Chapter 19, recommended for review queues.
- Age. The evidence carries a date and expires: by clock (this book uses 90 days as a default for verification evidence, the same default AI Leader used for usage evidence) and by condition, when the generator model, the codebase area or the specification changes.
Human reviewers are subject to the same pull towards agreement as everyone else. A systematic review of 74 studies found that users over-rely on automation and often fail to recognise the new errors that decision support introduces, with workload, time pressure and trust as mediators, and with training and emphasis on user accountability among the mitigators (43, Goddard et al., 2012). A further review found that complacency and automation bias occur in naive and expert participants alike and that automation bias cannot be prevented by training or instructions (57, Parasuraman & Manzey, 2010). In a study of security-relevant programming, participants with an AI assistant wrote less secure code and were more likely to believe it secure (34, Perry et al., 2023). An author who is more confident than the work warrants examines it less, and a tester who reviews a plausible drafted suite examines it less in turn. The remedy is design: write the expected result before reading the draft, seed faults, and keep the oracle's author apart from the change's author.
Exploratory testing and what stays human
Exploratory testing is where a person's knowledge of the domain and of the people who use the software is applied without a script. Nothing in the evidence reviewed here shows that a tool can take over that work. The studies above say something narrower: the tool can draft cases and can help a person explore, and the findings that matter most in public services, such as a form that is correct and unusable for a citizen with a screen reader, are found by people who look. The protected share of exploratory work is a decision for the quality lead, recorded in the verification plan, and it follows the AI Leader clause on the right to unassisted work.
Practical guide: keeping the oracle independent
Purpose. To show, for one change, that the checks that decide whether it is right do not depend on what generated it.
Roles. Quality engineer (accountable), developer (author of the change), product owner (owner of the specification), tech lead.
Inputs. The specification record with acceptance criteria; the change record; the delegation profile for the team; archived results from earlier production runs, where they exist.
Steps.
- Read the acceptance criteria in
SPC-*and list the properties the change must preserve, including the ones the incident history warns about. - Write the oracle for those properties before reading the generated tests or the generated code. Note any property for which no oracle can be written, and send it back to the product owner as an ambiguity.
- Let the assistant draft further cases only after step 2, and read them for what they assert. Discard or rewrite any case that restates the code.
- Seed faults: inject a small, recorded set of defects into a branch and run the suite. Record how many were caught.
- Record the oracle's owner, its source, the seeded-fault result, the date and the expiry in the verification plan.
- Re-run when the generator model, the module or the specification changes.
Artefact. A verification plan (VER-*) that names the oracle's owner and source.
A worked example for Hansa Mutual follows. The record is illustrative.
verification_plan:
  id: VER-HM-2030-0004
  change: CHG-HM-2030-0418
  service: SVC-HM-001            # claims core, payment instruction export
  specification: SPC-HM-2030-0011
  date: 2030-11-18
  author_of_change: developer, claims core delivery team
  generated_with: HM-DEV-001     # Mode 2, Level 1 Assisted
  oracle:
    owner: Ewelina Maj           # ROLE-HM-QA-01
    written_from:
      - SPC-HM-2030-0011 acceptance criteria AC-1 to AC-6
      - archived settlement runs of the last four quarter-ends
      - INC-HM-2029-0207 (312 claims paid twice)
    written_by_generator: false
    same_person_as_author: false
    properties:
      - a claim identifier appears in at most one payment instruction per run
      - instruction totals reconcile with the archived run totals
  drafted_tests:
    assistant: HM-DEV-002        # Level 1 Assisted, drafts only
    read_by: Ewelina Maj
    discarded_as_restating_code: 7
  seeded_faults: {injected: 10, caught: 9, run_on: 2030-11-18}
  exploratory_session: {minutes: 90, by: Ewelina Maj}
  review: two human approvals; an AI review comment does not count as one
  evidence_expires: 2031-02-16   # 90 days, or on change of model, module or SPC
  release_hold: quality engineer may hold at the manual gate
Quality as an independent voice
The quality function has always had a second job beside finding defects: it is a voice in the organisation that is not the voice of delivery. AI makes that job more important and harder, and this section says why independence matters organisationally, not only technically.
When code is cheap, the volume of change grows, and the pressure on the step that has to say "not yet" grows with it. If the only checks are those the delivery team writes and runs, the team that is rewarded for speed also marks its own work. A quality engineer who is able to say that the evidence for a release is old, partial or missing, and who is heard, is a control of the same kind as the observer in AI Operations: independent of what performed the action it verifies. Independence has three parts. The quality engineer needs access to the evidence without asking the team to produce it. The quality engineer needs the authority to hold a release at a defined gate, with a defined route to escalate. And the quality engineer must not be measured by delivery speed. This is the stewardship test Revert at the level of the release: someone has the authority, the access and the time to stop the change, outside the pipeline that shipped it.
Reporting lines are an organisational choice, and the two example organisations choose differently. A central quality function, as at Nordvik Region, gives structural distance and a single view across teams, at the cost of distance from the work. Quality engineers embedded in delivery teams, as at Hansa Mutual, give proximity and early involvement, at the cost of dependence on the team whose work they check. Neither structure is independent by itself. Independence is shown by evidence: the oracle's source and author, the seeded-fault results, the holds that were exercised and respected. A function that has never held a release may be sound, or may be unable to.
Claims about quality need the same discipline as any claim in this book. "The suite covers the settlement run" is a statement with a scope, a method, a date and a result. "Tests: 4,200, all green" is not. The AI Operations treatment of resilience applies unchanged: the board or the head of development should see what was tested, when and with what result, with "not tested" counted in the denominator (170, Nordqvist, 2026). A quality report that says only that coverage rose after the assistant was introduced reports a property of the tool and not of the software.
Measurement of the quality function itself is a hazard. Jerry Muller's argument in The Tyranny of Metrics is that measurement tied to reward invites distortion (100, Muller, 2018). Two metrics invite it in testing. Counting tests generated rewards volume. Counting defects found per tester rewards a tester for defects that a better specification would have prevented, and punishes one who works with the team early. Both also measure named staff. Where such measures concern named individuals they fall under co-determination: in Germany, section 87(1) no. 6 of the Betriebsverfassungsgesetz covers technical devices suited to monitor the behaviour or performance of employees (9, Germany, n.d.), and in Sweden the Co-determination in the Workplace Act, sections 10 to 12, gives a union a right to negotiate and, in section 11, requires the employer to negotiate before an important change (12, Sveriges riksdag & Regeringskansliet, 1976). Chapter 22 treats telemetry and employee rights. For this chapter the rule is the book's own conclusion: report quality by team, by service and by oracle, and never rank testers by counts of tests or defects.
Product owners
The product owner is, in the words of the Scrum Guide, accountable for maximising the value of the product resulting from the work of the Scrum Team and for effective Product Backlog management, the backlog being an emergent, ordered list of what is needed to improve the product (135, Schwaber & Sutherland, 2020). Two parts of that accountability change with AI.
Specification and acceptance
The first is the specification. Chapter 5 described the specification record as the place where intent is written down and tied to executable acceptance criteria. An assistant can draft user stories, propose acceptance criteria and ask clarifying questions. At Hansa Mutual, DLG-HM-DEV-01 allows specification drafting at Level 1 Assisted; at Nordvik Region, DLG-NR-DEV-01 keeps specify at Level 0 Advisory. In both, the product owner decides what is in scope and signs the record. The risk is the one Chapter 5 named: a plausible, fluent criterion that nobody examined. A drafted acceptance criterion that cannot be turned into an oracle is an ambiguity, and the tester is the person who finds that out first. In a team that works well, the quality engineer reads the criteria before the developer starts, because a criterion that cannot be checked is cheaper to fix than a feature that cannot be accepted.
The second is acceptance. The product owner accepts work against the criteria, on the evidence the quality engineer provides. If the criteria were drafted by the same assistant that drafted the tests and the code, acceptance becomes a ceremony in which one source agrees with itself. The product owner's counter is to own the criteria personally, to read them before generation, and to ask of every acceptance: whose oracle was this, and how old is the evidence?
Prototypes built by the owner
The third change is new: product owners build. With a chat assistant or a natural-language app builder, a product owner can produce a running prototype of a form, a flow or a report in an afternoon. An interview study of 22 product team members from enterprises, startups and academia describes the pattern as a workflow of four stages (ideation, generation, debugging and review). The participants reported faster iteration, support for creativity and lower barriers to participation, and also concerns about unreliable code, integration problems and over-reliance on AI; the authors describe new asymmetries of trust, responsibility and social stigma within teams, and raise deskilling, ownership and disclosure as questions (204, Li et al., 2025). The study is qualitative, the sample is small and self-selected, and it measures what participants reported, not delivery outcomes. It is evidence that the practice exists and what practitioners say about it, which is observable, and not evidence that it improves products.
A caution on self-report belongs here. In a randomised controlled trial of 16 experienced open-source developers completing 246 tasks in codebases they knew, allowing early-2025 AI tools increased task completion time by 19 per cent. Before the tasks developers predicted a 24 per cent reduction in time, and afterwards they estimated that the tools had cut time by 20 per cent (63, Becker et al., 2025). The setting was experienced developers in mature repositories, which is not a product owner's prototype, and the result does not transfer. What transfers is the method: a felt gain in speed and a measured one are different facts, and the claim "the prototype took an afternoon" is worth recording with its measure, including the time that developers later spent reading it.
The rule this book proposes is that a prototype is a question and not an answer. It is built to learn something about the need, with synthetic data, under a visible label, and it is never promoted as code. What is promoted is what was learned, written into the specification record. This keeps the benefit the interviewees describe and removes the main hazard, which is that a running screen looks finished. The line between prototype and production is treated further for citizen developers in Chapter 19.
Designers
The designer's craft moves in a similar direction. Before AI, the designer produced research, flows, mock-ups and a design system, and handed them to developers for implementation. With AI, a mock-up can become a running prototype with real interaction, and a designer can adjust the generated front end directly. The same interview study reports designers among the participants who use natural-language tools to produce prototypes (204, Li et al., 2025), with the benefits and concerns described above.
Three points matter for the boundary. First, the designer's accountability is the user's experience: the flow, the language, and the accessibility intent. A generated interface that follows the design system in appearance may still fail a user who navigates by keyboard or screen reader, so the designer and the accessibility specialist check the running prototype by using it. Nordvik Region has two designers and accessibility specialists in Applications and Integration, and the legal duties of accessibility in public services are the subject of Chapter 18; here it is enough to say that the check is a person's and is part of the oracle. Second, a designer who adjusts front-end code is changing a production artefact only if the code enters the repository. If it does, it follows the same path as any change: a named owner, review by a developer, the oracle and the pipeline. Third, the design system is a shared artefact whose owner must be named, because generated interfaces copy what they are given, including its defects.
The designer's gain is a shorter route from idea to something a citizen can try. The designer's risk is the same as the product owner's: a prototype that looks finished before the question it was built to answer has been answered.
Where the boundary moves
The boundaries between these roles and the developer are not fixed, and the following table states where they move and where they do not. The columns follow the developer functions; the last column states the rule that the book holds fixed.
| Activity | Function | Before generative AI | Now | What must not move |
|---|---|---|---|---|
| State the need and the criteria | D1 Frame | Product owner and analyst write; developers query | Assistant may draft; owner signs | The owner is named and signs the specification record |
| Build a throw-away prototype | D1 Frame, D3 Build | Designer mock-up; developer spike | Owner or designer builds a running prototype | It is labelled, uses synthetic data and is never promoted as code |
| Build the production change | D3 Build | Developer writes | Developer directs and reads generated code | A named developer understands the change |
| Write the oracle | D4 Prove | Tester designs cases from the specification | Quality engineer owns; assistant may draft cases | Written from the specification, not by the generator |
| Review the code | D4 Prove | Developer colleague | Developer colleague; AI comments advisory | An AI review comment never counts as a human approval |
| Check usability and accessibility | D4 Prove | Designer, accessibility specialist, tester | Same, on a running prototype | A person uses the software |
| Accept | D1 Frame | Product owner against criteria | Product owner against criteria and dated evidence | Evidence has an age and an owner |
| Hold or revert a release | D5 Steward | Release manager, team | Quality engineer may hold; owner reverts | Authority sits outside the pipeline |
Two movements deserve a sentence each. Prototype building has moved to the product owner and the designer, which widens who can frame a problem with something running. The drafting of tests has moved towards the tool, which narrows what the tester spends time on. Neither movement is a change in who is accountable.
The Level 4 prohibitions of the delegation ladder bear on this chapter in one place that is easy to miss. An agent may not be given Level 4 for a change to its own test oracles, review rules or pipeline gates. An agent that writes the code and the tests that decide whether the code passes, and that may also edit those tests when they fail, has altered the check on its own work. In every mandate, the oracle is out of reach of the agent that the oracle verifies.
A role-boundary matrix
A role-boundary matrix records, for a team, who frames, builds, proves and owns each kind of work, what AI may do in it and what is fixed. It is kept in version control beside the team's role charters (ROLE-*) and delegation profile (DLG-*), and it is reviewed when either changes.
Practical guide: building a role-boundary matrix
Purpose. To make explicit, for a team that includes testers, a product owner and a designer, where each role's accountability ends and where AI may take part.
Roles. Engineering manager or head of the unit (accountable), product owner, quality engineer, designer, tech lead, a developer, the union or works council representative for the review of any measure concerning named staff.
Inputs. The role charters of the team; the delegation profile with its ceilings per work class; the list of AI tools in use at which usage mode; the last incident or review that involved a handover between roles.
Steps.
- List the activities from need to revert, using the developer functions as the spine.
- For each, name the accountable role and the roles that may prepare it. Name a person, not a committee.
- Enter the highest degree of delegation the delegation profile allows for the matching work class, and the condition attached to it.
- Mark the fixed points: the oracle's independence, the unpromoted prototype, the named steward, the hold authority.
- Read it through with the people in it, and with the representatives where any entry concerns measurement of named staff. Record what they changed.
- Set a review date, normally with the delegation profile, and record the matrix in the team's repository.
Artefact. The matrix itself, as below. It has no identifier of its own in this book; it is an annex to the role charters and the delegation profile it names.
The following worked example is illustrative, for the e-services team of Nordvik Region.
role_boundary_matrix:
  team: e-services team, Applications and Integration, Nordvik Region
  service: SVC-NR-002              # citizen portal
  delegation_profile: DLG-NR-DEV-01
  role_charters: [ROLE-NR-DEV-01, ROLE-NR-DEV-02, ROLE-NR-QA-01]
  version: "1.0"
  adopted: 2030-10-21
  accountable_for_matrix: Gunilla Roos
  review_due: 2031-04-21
  activities:
    - {name: state the need and acceptance criteria, function: D1 Frame,
       accountable: product owner Hanna Wikström,
       prepares: [designer, quality engineer],
       ai: "specify, Level 0 Advisory"}
    - {name: build a prototype to learn, function: D1 Frame,
       accountable: the author of the prototype (owner or designer),
       ai: "generate, Level 1 Assisted; Mode 1 assistant",
       conditions: [synthetic data only, label PROTOTYPE, never merged, learning written to SPC]}
    - {name: build the production change, function: D3 Build,
       accountable: developer named in OWN record,
       ai: "generate, Level 1 Assisted; no generated file committed unread"}
    - {name: write the oracle, function: D4 Prove,
       accountable: quality engineer Saga Edvardsson,
       ai: "test, Level 1 Assisted for drafts; never the oracle for the same change"}
    - {name: review the code, function: D4 Prove,
       accountable: a developer colleague,
       ai: "review, Level 0 Advisory"}
    - {name: check usability and accessibility on the running service, function: D4 Prove,
       accountable: designer or accessibility specialist,
       ai: "none beyond Level 0 Advisory"}
    - {name: accept against criteria and dated evidence, function: D1 Frame,
       accountable: product owner Hanna Wikström}
    - {name: hold a release at the manual gate, function: D5 Steward,
       accountable: quality engineer; release proceeds only by recorded decision of the head of Applications and Integration}
    - {name: revert, function: D5 Steward,
       accountable: developer named in OWN record, outside the pipeline}
  fixed_points: [oracle independent of generator, prototype never promoted as code,
                 named steward, hold authority outside the pipeline]
  level_4_used: none
Across the usage modes
The table shows, for the roles of this chapter, what each usage mode looks like and the highest degree of delegation each organisation has allowed. It reports what the profiles in docs/EXAMPLE_ORGANISATIONS.md record; where an organisation has no tool at a mode, the cell says so.
| Usage mode | What it looks like for these roles | Nordvik Region | Hansa Mutual |
|---|---|---|---|
| Mode 0 Ambient AI | Completion in the IDE and in the ITSM tool; test code completed as it is typed | Within the generate ceiling of DLG-NR-DEV-01, Level 1 Assisted (decision recorded retrospectively, AIDR-1102) |
Within the generate and test ceilings of DLG-HM-DEV-01 |
| Mode 1 Conversational assistants | Product owner or designer drafts criteria or a prototype in chat | Level 1 Assisted; internal-classified material only | Level 1 Assisted for specify |
| Mode 2 Embedded workplace assistants | Developer or quality engineer drafts code and tests in the editor | Level 1 Assisted (pilot NR-DEV-001) |
Level 1 Assisted for test drafts; Level 2 Supervised for generate outside security-critical and payment paths |
| Mode 3 Agentic work tools | Agent drafts a change or a test suite in a sandbox and opens a pull request | Platform team only; not used by these roles | Level 2 Supervised for engineers; one Level 3 Bounded class (patch-level dependency updates), none for tests |
| Mode 4 Built AI applications | Purpose-built assistant such as a test-drafting service | None built for developers | HM-DEV-002 test drafting at Level 1 Assisted |
| Mode 5 Autonomous production agents | An agent that changes production on its own | None | None for coding; the operations agent acts under AI Operations |
No row reaches Level 4 Autonomous. For these roles, the prohibitions bear in three places: an agent does not change its own test oracles or review rules; security-critical and payment paths have a named human reviewer; and no tool decides about the employment, pay or performance rating of a named tester, owner or designer.
Nordvik Region and Hansa Mutual
Nordvik Region. The four testers and quality engineers of Applications and Integration form a quality function that serves the four product teams, which gives structural distance from any one team. The quality function is small relative to the work. A regression pack exists only for the portal and for the benefits workflow, and Saga Edvardsson owns the portal's pack and is the person who asks, of any proposal to let an assistant write tests, who writes the oracle. Among the five product owners and analysts, Hanna Wikström, product owner of the e-services team, builds prototypes herself with the Mode 1 assistant within the limits of the Mode 1 rule (no special-category data, no credentials, no benefits-triage rules). The Region's matrix for the e-services team, above, makes her prototypes unpromoted, labelled and built on synthetic data, and records the learning in a specification record such as SPC-NR-2030-0007. The two designers and accessibility specialists keep the check on the running service as part of the oracle. Measurement of named testers is not covered by MBA-NR-2029-02, which does not reach coding tools, and falls within the negotiation record MBA-NR-2030-03 opened in September 2030, which the IT representative of the union, Tomas Ekblad, asked to open before the Mode 2 pilot is extended. The recommendation of this chapter for the Region is to enter into that negotiation the rule that quality is reported by service and team and never by named tester.
Hansa Mutual. About 85 of the 480 people in Group Application Development are testers and quality engineers, working in some 62 delivery teams, which is on average between one and two per team. Ewelina Maj, test engineer at the Polish service centre, leads test automation of the settlement module and is the person who asks, again, who writes the oracle. The settlement history makes the question concrete: the post-incident review of INC-HM-2029-0207 found that a module with no owner who could explain the change had paid 312 claims twice. The verification plan VER-HM-2030-0004 above turns that incident into an explicit property of the oracle. Because embedded quality engineers depend on the team whose work they check, the delegation profile DLG-HM-DEV-01 fixes that the oracle for a change is written by someone other than the author of the change. The Konzernbetriebsrat co-determines under section 87(1) no. 6 of the Betriebsverfassungsgesetz, and the draft developer-tooling annex KBV-IT-2024-DEV-01 reports telemetry by team with a minimum group size of five and bars the use of acceptance rates in appraisal or pay; the Polish representatives and the Dutch ondernemingsraad have asked for the same terms. Counts of tests drafted by HM-DEV-002 per named engineer have no place under that annex. The roughly 60 product owners and analysts and the group's designers face the same prototype question as Nordvik's, with the larger organisation's added risk: the same prototype pattern repeated in dozens of teams without a common label.
Outlook
The chapter's statements about the future are labelled as in AI Governance, Chapter 22 (162, Nordqvist, 2026).
- Observable. Product team members, including designers and product managers, build running prototypes with natural-language tools, and they report faster iteration and concerns about reliability and over-reliance (204, Li et al., 2025). Mutation-guided generation of tests is deployed at one large company (195, Foster et al., 2025).
- Expected. Independent quality functions are expected to grow in importance within organisations that generate a large share of their changes, supported by a trend the evidence above describes: generation is getting cheaper, while the oracle, which is the human part of testing (178, Barr et al., 2015), is not. This is the book's own reading and is expected, not observed.
- Speculation. That testing as a role will end because models write tests is speculation. No study reviewed here shows an organisation that removed independent verification and achieved equal or better quality over several years, and the opposite claim, that testers will be needed in the same numbers, is equally unevidenced. What the thesis of this book says would show it wrong is multi-year evidence on organisations that let generators own their own oracles.
Summary
This chapter concerned D1 Frame and D4 Prove, the two functions on which the product owner, the designer, the tester and the quality engineer depend. The conclusions are the book's own. The boundary around intent and prototype moves outwards: product owners and designers can build running prototypes, and the discipline that keeps this useful is that a prototype is a question, labelled, built on synthetic data and never promoted as code. The boundary around proof and ownership does not move. The oracle is written from the specification by someone other than the author of the change and not by the generator, its independence is shown by its source, its author, seeded faults and an expiry, and a named person owns what reaches production and can stop it.
The tester's role shifts in weight from writing test code to owning the verification plan and exploring what no specification describes. Quality remains an independent voice only if it has access to evidence, the authority to hold a release at a defined gate and a measure of success that is not delivery speed. Quality is reported by team, service and oracle and never as a count per named tester, and where measures reach named staff, the works council or union is a party: the Konzernbetriebsrat at Hansa Mutual and the union branch at Nordvik Region. The product owner's accountability for value and acceptance is unchanged, and the specification record is where it is exercised.
Claims about speed and quality need evidence of the kind this chapter cited: what was measured, in whom, over what period and with what result. A felt gain and a measured one differ, as the trial of experienced developers showed. The role-boundary matrix makes the boundaries explicit in version control, and it carries no Level 4 for any class of work. Chapter 18 turns to the public authority, where procurement, public code and accessibility law bear on the same roles.
Sources
- Becker, J., Rush, N., Barnes, E. & Rein, D. (2025). Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity. METR; arXiv:2507.09089. (63, Becker et al., 2025)
- Barr, E. T., Harman, M., McMinn, P., Shahbaz, M. & Yoo, S. (2015). The Oracle Problem in Software Testing: A Survey. IEEE Transactions on Software Engineering 41(5), 507-525. (178, Barr et al., 2015)
- Just, R., Jalali, D., Inozemtseva, L., Ernst, M. D., Holmes, R. & Fraser, G. (2014). Are Mutants a Valid Substitute for Real Faults in Software Testing? FSE 2014, 654-665. (202, Just et al., 2014)
- Foster, C., Gulati, A., Harman, M., Harper, I., Mao, K., Ritchey, J., Robert, H. & Sengupta, S. (2025). Mutation-Guided LLM-based Test Generation at Meta. arXiv:2501.12862. (195, Foster et al., 2025)
- Itkonen, J. & Mäntylä, M. V. (2014). Are test cases needed? Replicated comparison between exploratory and test-case-based software testing. Empirical Software Engineering 19(2), 303-342. (203, Itkonen & Mäntylä, 2014)
- Li, J., Hou, Y., Lin, L., Zhu, R., Cao, H. & El Ali, A. (2025). Vibe Coding in Product Teams: Reconfiguring AI-Assisted Workflows, Prototyping, and Collaboration. arXiv:2509.10652. (204, Li et al., 2025)
- Schwaber, K. & Sutherland, J. (2020). The Scrum Guide. (135, Schwaber & Sutherland, 2020)
- Kim, E., Garg, A., Peng, K. & Garg, N. (2025). Correlated Errors in Large Language Models. ICML 2025; arXiv:2506.07962. (35, Kim et al., 2025)
- Goddard, K., Roudsari, A. & Wyatt, J. C. (2012). Automation bias: a systematic review of frequency, effect mediators, and mitigators. JAMIA 19(1), 121-127. (43, Goddard et al., 2012)
- Parasuraman, R. & Manzey, D. H. (2010). Complacency and Bias in Human Use of Automation: An Attentional Integration. Human Factors 52(3), 381-410. (57, Parasuraman & Manzey, 2010)
- Perry, N., Srivastava, M., Kumar, D. & Boneh, D. (2023). Do Users Write More Insecure Code with AI Assistants? ACM CCS '23; arXiv:2211.03622. (34, Perry et al., 2023)
- Muller, J. Z. (2018). The Tyranny of Metrics. Princeton University Press. (100, Muller, 2018)
- Federal Republic of Germany. Betriebsverfassungsgesetz (BetrVG), section 87. gesetze-im-internet.de. (9, Germany, n.d.)
- Sveriges riksdag, Regeringskansliet. Lag (1976:580) om medbestämmande i arbetslivet (MBL), 10 to 12 §§. (12, Sveriges riksdag & Regeringskansliet, 1976)
- Nordqvist, G. (2025). Architecture as Code. The Architecture as Code Series, Book 1. (161, Nordqvist, 2025)
- Nordqvist, G. (2026). AI Governance. The Architecture as Code Series, Book 2. (162, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Purple. The Architecture as Code Series, Book 9. (169, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Operations. The Architecture as Code Series, Book 10. (170, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Leader. The Architecture as Code Series, Book 11. (174, Nordqvist, 2026)