The Junior Developer and the Apprenticeship Problem
Every profession has a lowest rung where the work is easy enough to be done by someone who does not yet know the profession, and useful enough that doing it teaches the profession. This chapter asks what happens to that rung in software development when an assistant writes the small function, drafts the test and explains the unfamiliar module. It concerns D3 Build, because the tasks at issue are the making of code, and D4 Prove, because the skill that a junior most needs to acquire, and that the organisation most needs to be able to rely on, is the ability to judge whether a change is right. It is a debate chapter: it asks whether junior developers will disappear, states the case for concern and the case for calm at their strongest, and ends with a verdict and an artefact, the apprenticeship plan APR-*, that a tech lead and an engineering manager can put in version control on Monday.
The chapter builds on conclusions the earlier volumes reached for other roles. Architecture as Code (Chapter 18) managed competence as a skills matrix in a loop of assessment, planning, learning, application and measurement (161, Nordqvist, 2025). AI Governance, Chapter 14, assessed competence by practical demonstration and treated assessment results as personal data whose use is agreed with employee representatives (162, Nordqvist, 2026). AI Threat, Chapters 7 and 14, collected the evidence that learning without struggle weakens learning (165, Nordqvist, 2026). The Transformed Security Architect, Chapter 15, made keeping the craft a design decision (166, Nordqvist, 2026); AI Blue, Chapter 23, named the two halves of the apprenticeship problem (168, Nordqvist, 2026); AI Purple, Chapter 24, found the evidence on skill beside automation dependent on how the assistant is used (169, Nordqvist, 2026); AI Operations, Chapter 26, held that a thinning supply of entry-level operators is expected where organisations let it and that wholesale loss of the craft is speculation (170, Nordqvist, 2026); and AI Leader, Chapter 11, carried the problem to leadership (174, Nordqvist, 2026). This chapter takes the developer form, which the series states as open question Q19: where the next senior developers come from if the tasks that taught the craft are the tasks AI performs best.
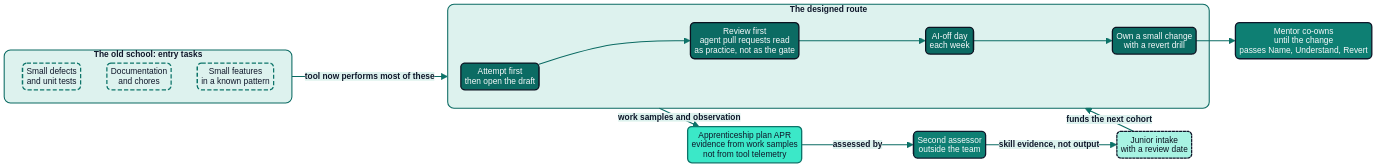
Figure 13.1: The designed apprenticeship route for a junior developer: attempt first, review first, an AI-off day each week and an owned small change with a revert drill, evidenced in a plan assessed by a second person and tied to a junior intake with a review date.
How juniors learned
Chapter 2 described what developers did before AI. The part of that description that matters here is how the craft was passed on. The account below is the book's own analysis, offered as a checklist and not as a finding from a study of how developers are made; the studies cited later in the chapter measure other things.
A junior developer in a European public authority or insurer of the 2010s and 2020s learned through a handful of recurring activities, and the activities were also the junior's job.
- Small defects in unfamiliar code. A defect with a reproducible symptom is a guided tour of a codebase. Finding the line teaches the structure, the conventions and the reasons for the odd parts.
- Tests for code someone else wrote. Writing a unit test for a function requires deciding what the function is supposed to do, which sends the junior to the specification, the ticket or the colleague who knows.
- Documentation and chores. Updating a README, bumping a dependency, renaming a field across a module: low risk, wide coverage, and the way a newcomer learns how the build, the repository and the release actually work.
- Small features in a known pattern. Adding a field to a form and a column to a table teaches the whole path from the screen to the database and the discipline of shipping something that someone else will run.
- Being reviewed. The review comment of a senior developer on a first pull request is the most concentrated teaching a junior receives, because it states the reason as well as the correction.
- Production exposure. A seat in the support rotation, a shadowed incident, the first revert. The junior learns that software has consequences and that someone owns them.
Two properties of this school matter before AI enters. The tasks were rarely valued for their output: a junior's defect fix was worth less than the hours of a senior who might have made it faster, so the organisation paid for the learning and was repaid when the junior became competent. And the school was informal. Few organisations recorded which tasks taught what, so the loss of one of them went unnoticed until later.
What AI changes
The tasks listed above are, with few exceptions, the tasks an assistant does best. A completion tool suggests the next line of a small function. A test-drafting assistant proposes unit tests for an existing method. An explainer summarises an unfamiliar module. An agent in a sandbox opens a pull request for a patch-level dependency update. In the two organisations of this book these tasks sit at specific degrees of delegation, and the delegation profiles show how much of the old school has moved.
| Entry task | What it taught | Who performs it now | Nordvik Region (DLG-NR-DEV-01) |
Hansa Mutual (DLG-HM-DEV-01) |
|---|---|---|---|---|
| Small defect in unfamiliar code | Reading code, tracing flow, reasons for odd parts | Assistant suggests the fix; explainer summarises the module | Generate Level 1 Assisted; migrate Level 0 Advisory | Generate Level 2 Supervised outside security-critical paths; Level 1 inside |
| Tests for existing code | What the code is meant to do; edge cases | Test-drafting assistant | Test Level 1 Assisted for drafts | Test Level 1 Assisted (HM-DEV-002); the oracle written by someone other than the author of the change |
| Documentation | Understanding by explaining | Assistant drafts, author checks | Document Level 2 Supervised | Document Level 2 Supervised |
| Chores and dependency updates | How the build and estate work | Agent or pipeline | Refactor Level 1 Assisted | Refactor Level 2 Supervised; patch-level dependency updates at Level 3 Bounded (MND-HM-DEV-01) |
| Small feature in a known pattern | The full path to production | Assistant generates, developer reads | Generate Level 1 Assisted | Generate Level 2 Supervised outside security-critical paths |
| Being reviewed | Judgement and the reasons behind it | Unchanged, but review capacity is strained by generated volume | Review Level 0 Advisory | Review Level 1 Assisted; an AI comment never counts as one of two human approvals |
The table shows two things. The delegation profiles do not remove the junior; they change the share of the junior's day spent on the activity that taught the craft. The ceilings are also ceilings, not usage. Ambient completion in the IDEs, switched on by default in the vendor's update of March 2030, operates at Mode 0 and was in use before the Region recorded any decision about it (AIDR-1102), which means that a junior who joined in August 2030 met the assistant before the first lesson.
A task has an output, which the tool can now supply, and a learning, which the tool supplies only if the junior does the thinking that the tool is replacing. The apprenticeship problem is the separation of those two. An organisation that sees only the output concludes that the task has gone; one that sees the learning asks where else it can happen.
What studies measured
The evidence falls into four groups, and they measure different things. None of them measures a European public authority or an insurer, and none of them measures the particular junior developer in a particular team. They are read here as signals, with their conditions.
Employment of early-career workers
Brynjolfsson, Chandar and Chen of the Stanford Digital Economy Lab use administrative payroll data from the provider ADP, covering millions of US workers through June 2026. In the revision of 12 August 2026 they report that employment of workers aged 22 to 25 in the most AI-exposed occupations is 19 per cent below where it would have been had it kept pace with less-exposed peers, that experienced workers show no comparable gap, that the adjustment runs mainly through reduced hiring of young workers and not through separations, and that the declines are concentrated in occupations where AI mainly substitutes for human tasks, while employment is flat or rising where it mainly complements. They state that the divergence persists when technology firms and computer occupations are excluded, that the gap has widened since they first documented it in August 2025, and that the results are early, descriptive indicators and not causal estimates. They also report that the divergence weakens when education is controlled for and that some divergent trends predate generative AI (51, Brynjolfsson et al., 2025). It is a working paper, not peer reviewed.
Hosseini and Lichtinger of Harvard approach the question from the firm. Using résumé data on about 65 million workers at more than 280,000 US firms from 2015 to 2025, they identify adopters of generative AI through job postings for "GenAI integrator" roles. Adopters are about 3.7 per cent of the firms, but larger than average. After adoption, junior employment in adopting firms falls relative to non-adopters, by about 9 per cent after six quarters, while senior employment trends remain largely unchanged; the decline is concentrated in the occupations most exposed to generative AI, exposed tasks are increasingly removed from junior job postings, and the decline is driven primarily by slower hiring and not by separations (69, Hosseini & Lichtinger, 2025). The identification of adoption through postings and the American setting are the limits of the claim.
A third study points the other way. Humlum and Vestergaard link surveys on chatbot adoption to Danish administrative labour market records and find precise null effects on earnings and recorded hours two years after the launch of ChatGPT, ruling out effects larger than 2 per cent; employers responded mainly by reorganising tasks (53, Humlum & Vestergaard, 2025). The study covers exposed occupations in general, not junior developers, and not hiring.
Read together, these studies make one point observable: in some American datasets, hiring of the youngest workers in the most exposed occupations is lower than in comparable occupations or firms, and the mechanism is fewer hires, not dismissals. They do not show that the cause is the substitution of an assistant for a junior, they do not cover Europe, and a Danish study of earnings and hours found no average effect.
Productivity of novices
Cui and colleagues pooled three randomised field experiments at Microsoft, Accenture and a Fortune 100 company with 4,867 software developers and report a 26.08 per cent increase in completed tasks for developers given an AI coding assistant; their abstract reports that less experienced developers adopted the tool at higher rates and gained more (176, Cui et al., 2024). The experiments are noisy and the outcome is completed tasks, not the quality of what was completed or what the developer later understood. In a study of 5,172 customer-support agents, access to a generative AI assistant raised issues resolved per hour by 15 per cent on average; less experienced and lower-skilled workers improved in speed and quality, the most experienced saw small gains in speed and small declines in quality, and the authors report evidence that the assistance facilitates learning (68, Brynjolfsson et al., 2025). That is a contact centre, not a software team.
Learning beside an assistant
Shen and Tamkin, in a preregistered preprint, asked 52 participants, 26 in each group, all with more than a year of Python experience, to complete two tasks with an unfamiliar asynchronous Python library, with or without an AI assistant, and then take a 27-point quiz without assistance. The assisted group scored 4.15 points lower, which the authors express as 17 per cent or about two grade points (Cohen's d = 0.738, p = 0.010), and the difference in completion time was not statistically significant. The authors attribute part of the control group's advantage to encountering and resolving errors independently. They describe six interaction patterns; the three that preserved learning, in which participants asked conceptual questions only, generated code and then asked follow-up questions, or asked for code together with explanations, scored 65 per cent or higher on the quiz, and the three that delegated the code or relied on the assistant for debugging scored between 24 and 39 per cent, with two to seven participants in each cluster (67, Shen & Tamkin, 2026). It is a small, short study of crowd-sourced participants, not a study of juniors in a team, and not yet peer reviewed.
Two older findings from other domains show the same shape. In a field experiment with nearly 1,000 high school mathematics students in Turkey, access to a GPT-4 interface raised grades on practice problems by 48 per cent; when access was removed, students who had used the standard interface scored 17 per cent lower than students who never had access, while a tutor with safeguards for learning raised practice grades by 127 per cent and largely avoided the later fall (66, Bastani et al., 2025). In a multicentre observational study in four centres in Poland, the adenoma detection rate in standard colonoscopy fell from 28.4 per cent before to 22.4 per cent after the introduction of AI-assisted colonoscopy (65, Budzyń et al., 2025). The settings are not software, and the second is observational, but both support the same reading: output with assistance and capability without it are different quantities, and a study that measures only the first says little about the second.
What none of them measured
No study cited here followed a cohort of junior developers in an enterprise or a public authority over several years, with and without a designed route, and measured time to independent ownership of a change. To the author's knowledge the effect of review-first learning or AI-off practice has not been measured in software teams; the designs in this chapter are the book's own conclusions, drawn from the evidence above and the earlier volumes, and the plan includes the measures that would test them. Deliberate practice, skill growth through effortful activity designed to improve performance, with feedback, comes from Ericsson, Krampe and Tesch-Römer (256, Ericsson et al., 1993); the chapter uses it as design vocabulary and not as an estimate of how much practice produces how much skill.
The debate
The question is whether junior developers will disappear. It is a useful question because it forces both sides to say which claim they hold: that fewer juniors are being hired now, that fewer will be needed, or that the learning they depended on is being removed.
The case for concern
The strongest version of the concern does not say that an assistant can do a junior's job. It says that an assistant can do the part of the job that the organisation values in the quarter, and that the part it cannot do is the part that justified hiring a junior at all. The reasoning has four steps.
First, the tasks that taught the craft are the tasks that assistants do best. A reproducible defect in a bounded function, a unit test for an existing method and a field added in a known pattern are the kind of work on which the studies cited above find the largest gains for less experienced people. Second, the payroll and résumé data show that the youngest workers in exposed occupations are hired less where adoption is high, through fewer hires and not through dismissals (51, Brynjolfsson et al., 2025), (69, Hosseini & Lichtinger, 2025); the mechanism is quiet, because no one is let go and no one decides to end a career route. Third, the learning that remains is at risk even for the junior who is hired. Unguarded assistance reduced understanding of a new library by about two grade points in one experiment (67, Shen & Tamkin, 2026) and reduced later performance in another (66, Bastani et al., 2025); the junior who delegates the first draft never meets the error that teaches. Fourth, the organisation needs the skill most where it has the least. AI Threat, Chapter 14, recorded the irony of automation: the person who supervises the machine needs the skill that the machine's reliability keeps them from using (165, Nordqvist, 2026). A review of generated code is supervision. The reviewer who has never written the kind of code under review cannot tell which parts are likely to be wrong.
Beneath the four steps lies an argument about incentives, which is the book's own analysis. A junior's training is an investment that the employer makes and the profession collects, because the junior may later move. When the entry tasks are cheap to automate, each employer saves by not hiring, and each decision is individually reasonable. The sum is a profession with too few developers who learned the craft the old way and too few who learned a new way, because no one built it. That is a risk, not a prediction.
The case for calm
The strongest version of the calm view starts from history. Every wave of tools changed what juniors did and none removed them: assemblers gave way to compilers, compilers to frameworks and open-source libraries, and each time the task that taught the craft moved, usually upward. The craft was not lost; the starting point shifted.
The evidence for the current wave is, on the calm reading, more favourable than the concern allows. The largest productivity gains in the field experiments accrued to less experienced developers, who also adopted the tools at higher rates (176, Cui et al., 2024); less experienced support agents improved in both speed and quality and showed signs of learning from the assistance (68, Brynjolfsson et al., 2025). The Danish study found no effect on earnings or hours two years on (53, Humlum & Vestergaard, 2025). The authors of the Stanford study themselves call their results descriptive, note that the gap weakens when education is controlled for and that some divergent trends predate generative AI (51, Brynjolfsson et al., 2025). The learning studies show that the assistant is not the problem and its use is: in the Shen and Tamkin experiment participants who asked conceptual questions scored 65 per cent or higher, and in the mathematics experiment a tutor with safeguards largely prevented the later fall (67, Shen & Tamkin, 2026), (66, Bastani et al., 2025). If the harm depends on a design choice, it can be designed away.
Finally, the calm view points to demand. If an assistant lowers the cost of a feature, organisations may want more software, and the work of understanding the problem, verifying the result and running the service grows with it. A junior who can work with an assistant and is asked to verify its output may be more useful than the junior of 2015. The studies cited here show no collapse of demand for developers, and an organisation that stops hiring juniors is making a bet that the evidence does not yet support.
Where the positions meet
The two positions agree on more than the debate in the press suggests.
- The route must be rebuilt, not assumed. The concern says the old school will not work unchanged and the calm view says something else will replace it; both require someone to design the replacement.
- Learning needs the attempt. Learning was preserved where participants did the thinking and lost where they delegated it. The sides differ only on how likely organisations are to design for it.
- The evidence is young and conditional. The employment data are American and descriptive; the key learning study is a preprint of 52 participants on a 35-minute task. None of it measures a junior in a European public authority.
- The decline in hiring is a choice, not a law. The mechanism in both employment studies is fewer hires, and an organisation that does not hire should know that it has decided.
- Skill is the measure, not output. An acceptance rate says nothing about whether a junior can explain the change. Both sides would measure time to independent ownership, the quality of reviews written and the ability to explain a module without the tool.
What can be done
The actions are specific to roles, and each is within the organisation's control.
- A junior developer states an attempt before opening the assistant's draft and keeps a short log of what the assistant got wrong.
- A senior developer or mentor protects two hours a week for the junior and reviews for reasons, not only corrections.
- A tech lead agrees an AI-off day, assigns pull requests to the junior for review as practice, and does not count that review as the gate until the plan says so.
- An engineering manager keeps a junior intake with a review date, measures skill and not output, and sets mentoring time against the intake and not against the sprint.
- A platform engineer configures the tools so that completion can be switched off for a named learning period without per-person telemetry.
- A works council or union representative receives the plan template before the first plan is signed and agrees which evidence it may contain.
Verdict
What the evidence shows, with the labels of AI Governance, Chapter 22, for the two functions concerned.
D3 Build. It is observable that tasks which once taught the craft are in many codebases performed in part by assistants, and that hiring of the youngest workers in the most AI-exposed occupations is lower in some American datasets, through fewer hires. It is observable, on the conditions of one small preregistered experiment, that unguarded assistance reduced learning of a new library and that some patterns of use did not. It is expected, because the decline is a decision by employers, that organisations which cut the junior intake without a replacement route will have fewer developers able to supervise generated code in a few years. It is speculation that the junior role will disappear, and equally speculation that juniors who use assistants will learn faster than their predecessors; no study measured either.
D4 Prove. It is observable that the stewardship principle of Chapter 4 depends on review, and that review is learned by writing, being reviewed and reviewing. It is expected that review capacity becomes the constraint in teams with a large volume of generated change, and that a junior never asked to review becomes a reviewer by title only. It is speculation whether assistants will review well enough to make human review of ordinary changes unnecessary; Chapter 9 treats the present evidence.
What people and organisations can influence is the intake, the design of the first year, the configuration of the tools, the measure of skill and the mentor's time. None of these depends on the outcome of the debate.
Designing the apprenticeship
An apprenticeship in this chapter is a first-year route with a named plan, a named mentor and a second assessor, which gives the junior real work, protected practice and recorded evidence. It need not be a formal apprenticeship scheme in the legal sense, though Hansa Mutual's is one. The design echoes the practices of AI Leader, Chapter 11 (attempt first, rotation in both directions, designed first rungs), adapted to the craft (174, Nordqvist, 2026).
Attempt first
The junior states what the problem is, what a solution would look like and where in the code it would go, before opening the assistant's draft. The attempt may be a paragraph in the ticket, a sketch of the test, a failing test written first or a question to the mentor. The attempt is recorded and not graded. The purpose is the one the Shen and Tamkin experiment points to: the interaction patterns that preserved learning involved the participant thinking before or after the tool, not instead of it (67, Shen & Tamkin, 2026).
Review first
Review-first learning turns the junior into a reader before a writer. In the first weeks the junior reads pull requests: human-written, agent-opened and, as an exercise, a small number with a defect known to the mentor (a seeded defect, planted in a training branch). The junior writes review comments, states the reason for each, and compares them with the mentor's. The point is to build the ability to judge generated code, which is the skill that D4 Prove requires and that the old school taught late.
One rule protects the design. The junior's review is practice, not the gate. A change that reaches production still passes the human review required by the delegation profile and the change policy, by a developer other than the junior, and a change in a security-critical path passes a named developer's review. A junior told to approve agent-opened pull requests to clear a queue has not been apprenticed but made a rubber stamp, and the test of Understand is passed by no one.
AI-off practice
AI-off exercises are tasks done without any assistant, including ambient completion, for a stated time. The plan sets a fixed share, for example one working day in five, and the exercises are real: tracing a defect in a legacy module, writing a test from a specification, explaining a module in writing, performing a revert. The share is a design choice and not a finding. No study has measured the right proportion, so the plan states the reason, records the evidence it collects and sets a review date at which the share is adjusted. The exercises also serve a second purpose that the earlier volumes named: they keep a record of what the practitioner can do without the tool, which is the degraded mode of D5 Steward when the tool is unavailable or wrong (166, Nordqvist, 2026).
Delegation to the junior and ownership
A junior is not delegated more than the profile allows, and may be delegated less. The plan sets the junior's own use of assistants below the team ceiling and raises it at milestones. The junior also learns ownership: the stewardship principle requires that a named developer can Name the change, Understand it without the tool and Revert it, so a junior who owns a small change, with the mentor as co-owner until it has passed those tests, learns the principle on a change small enough to revert.
Mentoring and the junior intake
Mentoring takes time that the sprint does not show. The plan budgets it in hours and treats it as part of the engineering manager's capacity. The junior intake is a decision with a review date: a team that reduces its intake records why, on what evidence and when the decision is reviewed, and the review compares skill evidence from the plans, time to independent ownership of a small change, the quality of reviews written, mentor hours and retention. It does not compare acceptance rates.
The European setting
Article 4 of the AI Act, as adopted in 2024, obliged providers and deployers to take measures to ensure, to their best extent, a sufficient level of AI literacy of their staff and others dealing with the operation and use of AI systems on their behalf, taking into account their technical knowledge, experience, education and training and the context of use (1, European Union, 2024). Regulation (EU) 2026/1744, the Digital Omnibus on AI, replaced it with a duty to take measures to support AI literacy, without a duty to guarantee a specific level for any individual (5, European Union, 2026). A plan that records what a junior learned about the tools, the limits of the delegation profile and the practice of checking is evidence of measures of that kind; Chapter 27 returns to the wording and to the competence record. In a German group, a tool suited to monitor the behaviour or performance of employees falls under co-determination in section 87(1) no. 6 of the Betriebsverfassungsgesetz (9, Germany, n.d.), which is why the plans take evidence from the mentor's observation and the junior's work samples and never from coding-tool telemetry on a named person; Chapter 22 treats the rights in full. In a public authority a graduate programme is also a continuity measure, because the legacy estate and the public code the Region publishes need people who can read them in ten years.
An apprenticeship plan
Practical guide: designing a first-year plan for a junior developer
Purpose. To give a new junior a first quarter of real work, protected practice and recorded evidence that does not depend on the tasks the assistants now perform.
Roles. The junior developer; the mentor (a senior developer in the team); the tech lead; the engineering manager or head of the unit, as owner; a second assessor from outside the team, for example a quality engineer or test engineer; a works-council or union representative, who receives the template; the data protection officer, for the handling of the plan as personal data.
Inputs. The team's delegation profile (DLG-*); the list of tools the junior has access to and their configuration; the team's code-ownership records (OWN-*); a list of five to eight real, small tasks from the backlog; the quarter's calendar.
Steps.
- List the entry tasks of the team and, for each, record what it taught and who performs it now (the table in the section on what AI changes is the template).
- Choose four to six milestones that cover reading code, writing a test from a specification, reviewing a pull request, owning a small change and reverting it. Phrase each as something the junior does and the mentor can observe.
- Set the junior's tool access by phase and write it into the plan, with the configuration the platform team applies.
- Fix the AI-off share and its reason, and name the exercises.
- Name the mentor and the second assessor, budget mentoring hours, and agree what evidence is kept: work samples, review comments, the junior's own log and the mentor's observation notes. Exclude coding-tool telemetry on the named person.
- Share the template with the employee representatives before the first plan is signed, and the plan with the junior.
- Sign the plan, commit it to version control with restricted access, and set review dates for the plan and for the junior intake.
Result. An apprenticeship plan APR-* that the owner, the mentor and the junior have signed, with a review date.
Worked example: APR-HM-2030-01
Aylin Demir joined the claims portal team of Hansa Mutual in September 2030 from the group's apprenticeship scheme (ROLE-HM-DEV-02). The plan below is illustrative, and the mentor is a fictional senior developer. It follows DLG-HM-DEV-01 (adopted 2030-09-30, AIDR-1153) and the interim terms of the developer-tooling annex under negotiation with the Konzernbetriebsrat (KBV-IT-2024-DEV-01).
# apprenticeship/plans/APR-HM-2030-01.yaml (illustrative)
id: APR-HM-2030-01
version: "1.0"
trainee: {name: Aylin Demir, role: ROLE-HM-DEV-02, team: claims portal team}
period: {from: 2030-09-02, to: 2030-11-29}
owner: Dr. Philipp Reinhardt        # head of Group Application Development
mentor: {name: Jörg Albers, hours_per_week: 2}   # senior developer, claims portal team
second_assessor: Ewelina Maj        # test engineer, Polish service centre
delegation_profile: DLG-HM-DEV-01
tool_access:                        # lower than the team ceiling in the first quarter
  - {weeks: "1-4",  assistant: HM-DEV-001, completion: off, chat: "explanations only, after an attempt is logged"}
  - {weeks: "5-8",  assistant: HM-DEV-001, completion: on,  chat: "after an attempt is logged"}
  - {weeks: "9-13", assistant: HM-DEV-001, completion: on,  agent_pull_requests: "read and review only"}
ai_off: {share: "1 day in 5", reason: "design choice, no study fixes the right share", review: 2030-11-29}
milestones:
  - {id: M1, week: 4,  does: "Explains the settlement-lookup module in writing and traces a known defect, assistants off", evidence: "written explanation, mentor notes"}
  - {id: M2, week: 8,  does: "Reviews five pull requests, two with defects seeded by the mentor, and states the reason for each comment", evidence: "review comments compared with mentor's"}
  - {id: M3, week: 11, does: "Owns one small change with a verification plan whose oracle is reviewed by the second assessor", evidence: "OWN record, VER record"}
  - {id: M4, week: 13, does: "Reverts her own change in the test environment, assistants off, within the agreed time", evidence: "revert log"}
review_rule: "Junior review is practice; a developer other than the junior gives the review that gates a merge."
evidence_excluded: [tool telemetry on a named person, acceptance rates]
use: "Development of the trainee only; not an input to appraisal, pay or ranking."
reviews: {plan: 2030-11-29, junior_intake: 2031-03-30}
competence_record: CMP-HM-2030-DEV-02
Three features are intended. The tool access starts below the team ceiling and rises with the milestones. The only evidence is what a person can observe and a work sample can show, so the plan does not become a monitoring instrument. The intake review falls on the same day as the review of DLG-HM-DEV-01 (2031-03-30), so that both decisions rest on the same evidence.
Across the degrees of delegation
The table shows, per class of development work, the ceilings in the two profiles and the additional rule the plan sets for a junior in the first quarter. No class is at Level 4 Autonomous, and the Level 4 prohibitions of the series hold: nothing in a junior's plan permits a change to production without a gate that the change cannot alter, code in a security-critical path without a named developer's review, a change to an agent's own mandate or test oracle, or an irreversible action on production data.
| Class of work | Nordvik Region | Hansa Mutual | Additional rule for a junior in the first quarter |
|---|---|---|---|
| Specify | Level 0 Advisory | Level 1 Assisted | Write the problem statement before opening any draft |
| Design | Level 0 Advisory | Level 0 Advisory | Attend design reviews; no AI draft counts as the design record |
| Generate | Level 1 Assisted | Level 2 Supervised outside security-critical and payment paths; Level 1 inside | Completion off in weeks 1 to 4; attempt logged before chat |
| Refactor | Level 1 Assisted | Level 2 Supervised | Refactor by hand on the AI-off day |
| Test | Level 1 Assisted for drafts | Level 1 Assisted for drafts; oracle by someone other than the author of the change | Write the oracle from the specification, then compare with the draft |
| Review | Level 0 Advisory | Level 1 Assisted | Review is practice, not the gate; an AI review comment never counts as one |
| Deploy | Level 0 | Level 0 | Shadow the release; no tool acts on it |
| Operate | Level 0 Advisory | Level 0 Advisory | Shadow the support rotation, never alone in the first quarter |
| Document | Level 2 Supervised | Level 2 Supervised | Explain in writing before reading the draft |
| Migrate | Level 0 Advisory | Level 0 Advisory | Read legacy code before using any explainer |
The people class is not delegated in either profile. It follows that the assessment of the junior is made by named people, the mentor and the second assessor, and that no assistant drafts it, ranks it or feeds it into a rating.
Nordvik Region and Hansa Mutual
Nordvik Region recruits juniors through a graduate programme and apprenticeships. Applications and Integration has 18 developers, two of them juniors: Emil Nordgren, who joined in August 2030 from the graduate programme and works on the case platform team, and Frida Lund in the e-services team. The first-quarter plan APR-NR-2030-01 (2 September to 29 November 2030, owner Gunilla Roos) names Linnea Sjöberg, senior developer on the case platform team, as Emil's mentor with two protected hours a week, and Saga Edvardsson, who owns the portal's regression pack, as second assessor. The case platform is a Java 8 system of about 1.1 million lines with low test coverage on the inherited parts, a good school for reading code; the first month's AI-off exercise is to trace a defect through the PL/SQL and Java layers with completion off. Emil was not in the pilot NR-DEV-001, whose reported acceptance rate of 31 per cent and four hours saved a week (AVR-NR-2030-01, evidence five months old when the plan began) say nothing about learning. Ambient completion has been on by default since March 2030, so the platform team switches it off for the learning period. The union representatives received the template before the first plan was signed. Chapter 18 takes forward, for tender NR-2030-041, the requirement that a procured assistant can switch completion off per user for a defined period and export logs without per-person telemetry. The Region keeps its 2031 intake of two juniors independent of the tender and reviews it on 2031-03-23 with DLG-NR-DEV-01.
Hansa Mutual reduced its junior intake in one team in 2030. The head of the broker interface team, citing the figure of 42 per cent of committed lines as AI-assisted that had gone to the executive board in February 2030, took no apprentices for the 2030 intake (illustrative). The figure counted accepted suggestions as a share of lines; a sample of 40 merged pull requests in August 2030 found 27 per cent of lines traceable to an accepted suggestion, with no measure of whether they stayed (AVR-HM-2030-01). Neither number measures the tasks an apprentice would have done (Chapter 20 treats the measurement). The group reviews the decision on 2031-03-30 with the evidence of the plans. The policy administration platform is the other place to watch: 12 COBOL and PL/I developers maintain about 6.5 million lines, five within eight years of retirement, and a legacy-code explainer HM-DEV-003 is in pilot at Level 0 Advisory with four of them. A route for people to learn that estate is a continuity question for D5 Steward (Chapter 12), and the plan's rule to read legacy code before using any explainer comes from there. In both organisations the plans exclude coding-tool telemetry on a named person; the draft annex KBV-IT-2024-DEV-01 also excludes acceptance rates from appraisal and pay, with reporting by teams of five or more.
Summary
The tasks that taught software craft, small defects, tests for existing code, documentation, chores, small features and the first review, are the tasks assistants perform best, and in the delegation profiles of Nordvik Region and Hansa Mutual part of them already sits at Level 1 to Level 3. What the tasks carried is a learning, which moves to the tool unless the junior does the thinking. The apprenticeship problem is the separation of output from learning: where the next senior developers come from, and how present ones keep a skill their tools no longer exercise.
The studies measured four different things: lower hiring of the youngest in exposed occupations in some American datasets, through fewer hires; higher output for less experienced workers; learning beside an assistant, which depends on the pattern of use and fell in the unguarded cases; and, in no study, the effect of a designed route. The case for concern is that the incentive to hire juniors and the learning are eroding; the case for calm is that every wave moved the entry tasks and that the harm depends on design. The positions meet on four points: the route must be rebuilt, learning needs the attempt, the evidence is young, and the decision to hire is the organisation's.
The verdict labels it observable that hiring of the youngest is lower where adoption and exposure are high and that unguarded assistance can reduce learning, expected that organisations without a designed route will have a thin supply of developers able to supervise generated code, and speculation that the junior will disappear. The design is the book's own conclusion: attempt first, review first, AI-off practice, ownership of a small change with a revert drill, a mentor and a second assessor, evidence from work and not from telemetry, and an intake with a review date. The junior's review is practice, not the gate; the people class is not delegated, and no assistant assesses a named junior.
This chapter concerned D3 Build and D4 Prove. The reader who wants one thing to do can take the plan above, replace the names and milestones with the team's own and put it in version control before the next junior arrives. Chapter 14 turns to the senior developer on whom the plan depends.
Sources
- European Parliament and Council of the European Union. Regulation (EU) 2024/1689 laying down harmonised rules on artificial intelligence (Artificial Intelligence Act). Official Journal of the European Union, 12 July 2024. (1, European Union, 2024)
- Federal Republic of Germany. Betriebsverfassungsgesetz (BetrVG), section 87 (Mitbestimmungsrechte). Federal Ministry of Justice, gesetze-im-internet.de. (9, Germany, n.d.)
- European Parliament and Council of the European Union (2026). Regulation (EU) 2026/1744 amending Regulations (EU) 2024/1689, (EU) 2018/1139 and (EU) 2023/1230 as regards the simplification of the implementation of harmonised rules on artificial intelligence (Digital Omnibus on AI). Official Journal of the European Union, 24 July 2026. (5, European Union, 2026)
- Brynjolfsson, E., Chandar, B. & Chen, R. (2025, revised 12 August 2026). Canaries in the Coal Mine? Six Facts about the Recent Employment Effects of Artificial Intelligence. Stanford Digital Economy Lab. (51, Brynjolfsson et al., 2025)
- Humlum, A. & Vestergaard, E. (2025). Still Waters, Rapid Currents: Early Labor Market Transformation under Generative AI. NBER Working Paper 33777. (53, Humlum & Vestergaard, 2025)
- Budzyń, K., Romańczyk, M. et al. (2025). Endoscopist deskilling risk after exposure to artificial intelligence in colonoscopy: a multicentre, observational study. The Lancet Gastroenterology & Hepatology 10, 896-903. (65, Budzyń et al., 2025)
- Bastani, H. et al. (2025). Generative AI without guardrails can harm learning: Evidence from high school mathematics. Proceedings of the National Academy of Sciences 122(26), e2422633122. (66, Bastani et al., 2025)
- Shen, J. H. & Tamkin, A. (2026). How AI Impacts Skill Formation. arXiv:2601.20245. (67, Shen & Tamkin, 2026)
- Brynjolfsson, E., Li, D. & Raymond, L. R. (2025). Generative AI at Work. The Quarterly Journal of Economics 140(2), 889-942. (68, Brynjolfsson et al., 2025)
- Nordqvist, G. (2025). Architecture as Code. The Architecture as Code Series, Book 1. (161, Nordqvist, 2025)
- Nordqvist, G. (2026). AI Governance. The Architecture as Code Series, Book 2. (162, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Threat. The Architecture as Code Series, Book 5. (165, Nordqvist, 2026)
- Nordqvist, G. (2026). The Transformed Security Architect. The Architecture as Code Series, Book 6. (166, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Blue. The Architecture as Code Series, Book 8. (168, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Purple. The Architecture as Code Series, Book 9. (169, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Operations. The Architecture as Code Series, Book 10. (170, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Leader. The Architecture as Code Series, Book 11. (174, Nordqvist, 2026)
- Cui, Z. (K.), Demirer, M., Jaffe, S., Musolff, L., Peng, S. & Salz, T. (2024). The Effects of Generative AI on High-Skilled Work: Evidence from Three Field Experiments with Software Developers. SSRN 4945566; Management Science. (176, Cui et al., 2024)
- Hosseini, S. M. & Lichtinger, G. (2025, version of 6 May 2026). Generative AI as Seniority-Biased Technological Change: Evidence from U.S. Résumé and Job Posting Data. SSRN 5425555. (69, Hosseini & Lichtinger, 2025)
- Ericsson, K. A., Krampe, R. T. & Tesch-Römer, C. (1993). The role of deliberate practice in the acquisition of expert performance. Psychological Review 100(3), 363-406. (256, Ericsson et al., 1993)