Prove: Review, Tests and Verification
A change that reaches production has to be shown to be right by something other than the thing that produced it. This chapter treats that showing, D4 Prove: code review, testing strategy, static analysis and the places where formal methods earn their cost, and what each of them can and cannot establish when AI wrote the diff, drafted the tests or wrote the review comment. It touches D3 Build, because the volume of what is built sets the load on what must be proved, and D5 Steward, because proof that nobody can act on has no owner. Chapter 8 defined the mandate under which a coding agent produces a change. This chapter defines what the change has to pass before a named developer can accept it, and Chapter 10 takes the security-specific checks and the toolchain as an attack surface.
The chapter makes one argument. Generation became cheap and verification did not, so the checks that show a change to be right carry more weight and are more exposed to correlated failure. A check counts as proof only when its failure modes are shown not to be those of the thing it checks. That is the independence principle of AI Purple, Chapter 15 (169, Nordqvist, 2026), and the observer principle of AI Operations, Chapter 17 (170, Nordqvist, 2026), applied to code. In this book it appears as the corollary of the stewardship principle defined in Chapter 4: the test oracle must be independent of the generator. A test oracle is the mechanism that decides whether the observed behaviour of the software is correct, whether a human reading the output, an expected value in a test, a stated property or a reference implementation.
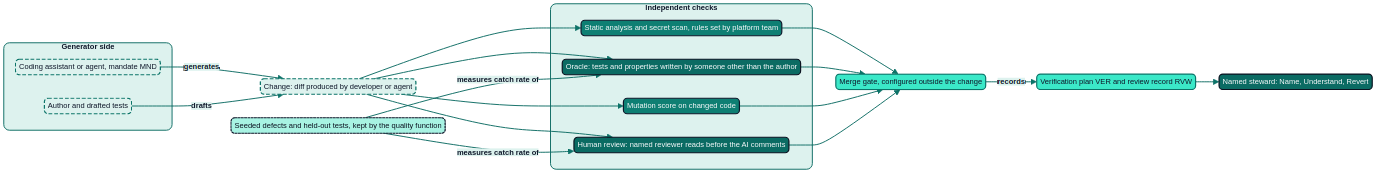
Figure 9.1: Evidence of correctness across independent checks. The generator side drafts the change and its tests; the checks that count are set and kept outside it, and a named steward receives the record.
What review is for
Code review is the oldest check in the chain and the one that has been given the most unexamined trust. Its purposes are more varied than its name suggests, and the evidence on them predates generative AI, which matters because it describes what review was already good at before the volume problem arrived.
Bacchelli and Bird observed, interviewed and surveyed developers and managers at Microsoft and classified hundreds of review comments by hand. They found that finding defects remained the main stated motivation for review, while reviews delivered less defect detection than people expected and delivered other outcomes alongside it, among them knowledge transfer and team awareness. They also found that understanding the code and the change was the central activity of a review, and that most of the means developers use to gain that understanding were not supported by the tools of the time (190, Bacchelli & Bird, 2013). Sadowski and colleagues studied review at Google with 12 interviews, a survey of 44 respondents and an analysis of review logs covering about 9 million reviewed changes, to ask why the practice was adopted, how it is carried out and what developers find satisfying or difficult (191, Sadowski et al., 2018). Czerwonka, Greiler and Tilford, in a short position paper from Microsoft, argued that reviews often do not find functionality problems that should block a submission, that effective review needs reviewers with a particular set of skills, and that the current best practice slows teams down (192, Czerwonka et al., 2015). These are studies of two large software organisations, an interview-and-survey design and a position paper. They do not give an effect size for defects caught, and this chapter does not construct one.
Read together, they support a plain conclusion that is the chapter's own: review is a mixed instrument. It finds some defects, it spreads knowledge of the codebase, it enforces conventions, and it creates a second person who can say what the change does. For the stewardship principle the last of these is the one that matters. The Understand test asks whether the owner can explain the change without the tool that generated it, and a reviewer who has read and questioned a diff is a second person who can. A review that has none of these effects, because the approval came within seconds, has produced a signature and nothing else. AI Governance, Chapter 10, recorded the same rule for human oversight of decisions: oversight must be designed, with an interruption path and an override log, and approvals given in seconds are a signal of rubber-stamping (162, Nordqvist, 2026).
What the regulatory texts ask
The legal texts that touch software development ask for review and testing without saying who or what performs them. Commission Delegated Regulation (EU) 2024/1774, which supplements the Digital Operational Resilience Act (DORA, Regulation (EU) 2022/2554) with regulatory technical standards for ICT risk management, requires in Article 16(2) that financial entities test and approve ICT systems before use and after maintenance, including the quality of internally developed software, in proportion to the criticality of the business procedures and assets. Article 16(3) requires a procedure that includes source code reviews using both static and dynamic testing, to identify and analyse vulnerabilities and anomalies in the code, with an action plan that is monitored. Article 16(8) requires proprietary software and, where feasible, code from ICT third-party providers and open-source projects to be analysed and tested in accordance with paragraph 3 before it is deployed in production (15, European Commission, 2024). The NIST Secure Software Development Framework asks the producer to determine whether code review, by a person, in a fully automated way or in combination, will be used (practice PW.7), and to test executable code to identify vulnerabilities and verify compliance with security requirements (PW.8) (232, Souppaya et al., 2022).
The architectural implication is the same under both texts. The duty attaches to the change and to the organisation that deploys it, whoever or whatever wrote it. For Hansa Mutual's EU entities the DORA texts apply to code an agent drafted, to code of the nearshore partner and to code of an open-source library, and Article 16(3) in particular describes a procedure of source code review with static and dynamic testing, which a review that only read a diff would not meet. Article 14(4)(b) of the AI Act asks that people assigned to oversee a high-risk AI system remain aware of the possible tendency of automatically relying or over-relying on its output (1, European Union, 2024). That article concerns the oversight of high-risk AI systems and does not govern a developer reviewing a coding assistant's diff. It is cited here because it names the same hazard in law, and because both organisations deploy systems to which it applies (Chapter 24 maps the instruments to duties).
Testing strategy
A testing strategy is a decision about which kinds of check answer which kinds of question, and what each costs. Architecture as Code (Chapter 13) set out testing strategies for infrastructure as code and the place of tests in the pipeline (161, Nordqvist, 2025); this chapter does not repeat that practice. It asks what changes when a share of the code and of the tests is generated.
The layers and what each answers
Unit tests answer whether a function does what its author expected. Integration tests answer whether components agree at their boundaries. Both are example-based: a developer chooses inputs and states the expected output, and the strength of the test is the strength of the examples. Example-based tests have a known weakness for generated code, which tends to satisfy the examples it was shown and to differ on the ones it was not.
Property-based tests state a rule that must hold for all inputs of a kind and let a tool generate the inputs. Claessen and Hughes introduced the approach in QuickCheck: the developer writes properties as formulae and the tool checks them on randomly generated inputs, reporting a failing case (199, Claessen & Hughes, 2000). A property for a claims calculation might say that the payout is never negative, never exceeds the sum insured and does not decrease when the covered loss increases. Such a property is short and is derived from the policy wording, not from the code, which is why it works well as an independent oracle: whoever writes it needs no knowledge of how the implementation was produced.
Mutation testing measures the strength of a test suite by changing the code on purpose. A tool makes small modifications to the code, each called a mutant, and runs the tests; a mutant that no test fails is a live mutant and marks a behaviour that the suite does not pin down. Petrović and colleagues analysed about 15 million mutants in the code review process at Google. They report that developers who used mutation testing wrote more tests and improved their suites with higher-quality tests, leaving fewer surviving mutants, and that in an analysis of fixes for real high-priority faults a surviving mutant would have been reported at the change that introduced the fault (194, Petrović et al., 2021). The setting is one company's tooling and review workflow, and the result tells a team what mutation testing did there; it does not establish a threshold for the score that other teams should demand. Foster and colleagues describe a system at Meta, ACH, that uses an LLM to write tests aimed at mutants that represent a stated concern, in their case privacy. Across 10,795 Android Kotlin classes it produced 9,095 mutants and 571 privacy-hardening test cases; engineers accepted 73 per cent of the generated tests in test-a-thons and judged 36 per cent of them privacy-relevant (195, Foster et al., 2025). The report is the authors' own, from an industry track, and covers acceptance by engineers at a particular moment. It shows that mutation and generated tests can be combined in a loop in which the mutant, not the generator, defines what a good test is, and that is the property this chapter uses.
Static analysis checks code against rules without running it. Sadowski and colleagues described what Google learned from building such tools: developers must find the tools worthwhile, and integration in the developer's workflow was the key to adoption (197, Sadowski et al., 2018). In an AI-assisted workflow it is the cheapest independent check: its rules are written once by people who did not write any particular diff and apply identically to human and generated change. It removes from the reviewer the defects and conventions a program can find, so that attention goes to what only a person can judge.
Formal methods at the edge
Formal methods prove properties of a specification or a program by reasoning, not by sampling. Their cost is high and their reach is narrow, and the sensible use is at the edge of a system where an error is expensive and the property can be stated precisely. Newcombe and colleagues report that engineers at Amazon Web Services have used formal specification and model checking, with TLA+, since 2011 to help solve difficult design problems in critical systems (198, Newcombe et al., 2015). The account is from the users, about design-level specifications of distributed systems, and it does not say that whole programs were proved correct. For a public authority or an insurer the candidates are a state machine for case status or the rules that decide when a payment run may start; a model of such a rule is also an oracle that does not share the blind spots of the code. Whole-system machine-verified correctness for ordinary enterprise software is, on the evidence reviewed here, speculation.
The division of labour
The layers are not interchangeable, and a strategy that states which layer answers which question is the first step towards a verification plan. The table is the book's own synthesis of the studies above and of the independence dimensions of AI Purple; it is not a finding.
| Check | Question it answers | Who or what should write it | Typical blind spot |
|---|---|---|---|
| Static analysis | Does the change break a rule that can be stated? | Platform team or security function, once | Intent; anything that is not a stated rule |
| Example-based test | Does the code give the expected result for these inputs? | A person other than the author for the oracle; the assistant may draft | Inputs nobody thought of |
| Property-based test | Does a rule hold for all inputs of a kind? | A person from the specification, not from the code | Properties that are too weak or never stated |
| Mutation score | Would the suite notice if this behaviour changed? | A tool, set by the quality function | Equivalent mutants; a score that becomes a target |
| Formal model | Does the design satisfy this rule in all states? | A specialist, with the product owner | The gap between model and code |
| Human review | Is the change understood and acceptable? | A named developer who did not write it | Fluency; volume; shared assumptions |
The independent test oracle
The previous section assumed that someone writes the checks. This section asks who, because the answer decides whether the checks verify anything. Barr and colleagues surveyed the oracle problem in software testing and concluded that the lack of oracles is a bottleneck for test automation; the survey discusses oracle techniques such as specifications, contracts and metamorphic testing, in which the relation between the outputs for related inputs, and not an expected value, is checked (178, Barr et al., 2015). The oracle problem was a bottleneck long before AI wrote code. What AI changes is that the cheapest way to fill the bottleneck is to ask the generator for the tests too.
Why tests written for the same change verify less than they appear to
A test written by the author of a change, or generated from the same prompt and the same context, tends to encode the same understanding as the code. If the understanding is wrong, both are wrong in the same way, and the test passes. This is not a defect of any tool; it is a property of authorship, and it holds for a human who writes the test straight after the code. Generated code makes it sharper in two respects. An assistant asked to write tests for existing code derives the expected values from what the code does, and a suite built that way records behaviour; it does not specify it.
Liu and colleagues give a measurement of the related effect on benchmarks. They extended the test cases of the HumanEval code-generation benchmark by a factor of 80 and reported that the pass@k of the evaluated models fell by up to 19.3 to 28.9 per cent, because code that passed the original, thinner tests failed on the added ones (193, Liu et al., 2023). The setting is a benchmark of short function-level tasks and 2023 models; the conclusion that transfers is the chapter's own: a pass is as strong as the oracle behind it, and a green suite does not show whether it is thin.
The rule
The stewardship principle states the corollary: the test oracle must be independent of the generator. This book operationalises the corollary as three rules, each of which can be checked in a record.
- Authorship. The oracle for a change, whether examples, properties or a reference model, is written or approved by a person other than the author of the change. Where the change was generated, the person who prompted it and the assistant that produced it count as the author. An assistant may draft test code, but a named person who did not write the change reads the oracle and owns it.
- Source. The oracle is derived from a source that the implementation was not derived from: the specification record (
SPC-*), the policy wording, the statute, a previous version's recorded results or a domain expert's cases. A test derived from the code under test is a regression test, which is useful and answers a different question. - Protection. The agent or assistant that produces the change has no permission to edit the oracle, the review rules or the pipeline gate for that change. Level 4 is never used for a change to the agent's own test oracles, review rules or pipeline gates.
The rules do not make the oracle perfect; they make its errors different from the generator's, which is what independence means. AI Purple, Chapter 15, listed dimensions along which independence can be shown: model, data, authorship, vendor and time, and showed it with held-out cases written by people and seeded errors (169, Nordqvist, 2026). AI Operations, Chapter 17, added that a model checking a model is a partial remedy when errors among capable models are correlated, and that scripts and synthetic transactions are preferred to a second model where they can be had (170, Nordqvist, 2026). The same holds here. When the question is whether a pricing rule is applied correctly, a property derived from the tariff table is a better oracle than a second model's reading of the code.
Practical guide: Writing a verification plan with an independent oracle
Purpose. Record, before the change is merged, what will show it right, who wrote each check and what independence each check has from the generator.
Roles. The developer or tech lead who owns the change; a tester or quality engineer who writes or approves the oracle; the named reviewer; where the change is in a security-critical path, a named developer with the standing to review it; the platform engineer who holds the gate.
Inputs. The specification record SPC-* or the ticket's acceptance criteria; the delegation profile DLG-* and the mandate MND-* under which any agent worked; the run record RUN-* where an agent produced the change; the code-ownership record OWN-*.
Steps.
- Name the behaviour that must be true after the change and the behaviour that must not change. Take both from the specification, not from the diff.
- Choose the layers from the table above. For every layer, name who writes the check and the source of the expected result.
- Write the properties first and have them reviewed against the specification by someone who has not read the diff.
- Set the mutation target for the changed lines and name who may lower it. Record that the author cannot.
- List the checks the generator can see and those it cannot, and record that the agent has no edit right to the second group.
- Add a differential check where a reference exists: run the old and the new behaviour on recorded inputs and explain every difference.
- Name the reviewer and state what they read first. Reviewers read the specification and the plan before any AI-written summary or comment.
- Name the steward and record how the change is reverted, by whom, outside the pipeline that shipped it.
Artefact. A verification plan VER-* committed with the change, and a review record RVW-* written at merge. The next section shows both.
The volume problem
Cheap generation changes the load on review in a way that no study of review before 2023 measured. Three observations bear on it, and none of them is a measurement of review quality under AI.
The first is that adoption is wide and trust is not. The 2025 Stack Overflow Developer Survey, answered by over 49,000 self-selected respondents, found that 45.7 per cent distrust the accuracy of AI tools and 3.1 per cent highly trust it; the most frequent frustration, named by 66 per cent, was solutions that are almost right but not quite (217, Stack Overflow, 2025). The survey measures what respondents say, from a self-selected sample. It reports the condition that makes review hard: output that is almost right must be read closely to find where it is not.
The second is that the programme that has measured delivery performance for years found the effect on stability to be negative. The DevOps Research and Assessment (DORA) programme's 2024 report states that AI adoption increases individual productivity, flow and job satisfaction, and also negatively affects software delivery stability and throughput (216, Google Cloud, 2024). The 2025 report, based on nearly 5,000 survey respondents, reports a positive relationship between AI adoption and throughput and a continuing negative relationship with stability, and it attributes the instability to change volume that outruns the control systems downstream: strong automated testing, mature version control and fast feedback loops (42, Harvey & DeBellis, 2025). Both are surveys of self-reported practice, and the second is read here from the programme's announcement.
The third is a user study. Perry and colleagues asked participants to complete security-related tasks with and without an AI assistant. Those with the assistant wrote significantly less secure code and were more likely to believe that their code was secure (34, Perry et al., 2023). The study covers one assistant of 2022 and did not study review; it matters because a reviewer who shares the authors' confidence is less likely to look for what it found. Automation bias, the tendency to rely on automated output, has been documented in a systematic review of studies (43, Goddard et al., 2012) and it is the reason the design of review, not the exhortation of reviewers, has to carry the weight. Chapter 7 treats the productivity studies; one randomised trial with experienced developers in their own repositories found tasks took 19 per cent longer with AI allowed while the developers believed they had been faster (63, Becker et al., 2025). It did not isolate review, and is cited only because a team's sense that review is keeping up is a perception that measurement can contradict.
What the arithmetic says
The conclusion that follows is the chapter's own and rests on arithmetic, not on a study. Review capacity is a finite quantity of attention, and merge rate is bounded by it. If a team's assistants raise the number of pull requests per week and their size, and the reviewing hours stay the same, one of three things happens: the queue grows, the review per change gets thinner, or the volume is capped. Only the third is a decision. The first two are what happens when nobody decides. For illustration, a team with thirty-two careful review hours a week and a forty-five-minute review per diff can review about forty-two diffs. If assistants raise the weekly count to sixty, the average budget falls to about thirty-two minutes, or the team approves faster than it reads. The numbers are invented; the structure is not.
Designing review so that it stays real
AI Leader, Chapter 19, set out the design rules for reviewing the work of specialists whose fluency can be mistaken for competence: review starts from the reviewer's first judgement, is disclosed, seeded, partly unassisted and budgeted, and is never delegated to a second model alone (174, Nordqvist, 2026). The Transformed Security Architect, Chapter 14, applied it to the architect who verifies what AI proposes (166, Nordqvist, 2026). For the developer the rules become the following.
- Size limits and stacking. A change above an agreed size is returned to be split. The limit is a property of the pipeline, not of the reviewer's willingness.
- Description before diff. The author, or the agent, states what the change is meant to do, which tests it passes and which it changed. The reviewer compares the diff with the specification before reading any AI-written summary.
- A review budget and a queue cap. The team records its review hours and the number of open changes it will carry. When the cap is reached, new generation waits. Agents that open pull requests have a per-agent limit in their mandate.
- Seeded defects. The quality function adds known defects to a sample of changes and measures how many are caught by each check, by the human reviewer and by the AI reviewer. Seeding is announced to the teams in advance as a standing practice, reports the catch rate by check and by team, and is never aimed at a named developer. If the catch rate falls, delegation is lowered until it recovers.
- Rotation. Reviewers rotate across areas so that familiarity does not turn into the habit of approving.
- An unassisted share. A fixed share of reviews is done without AI summaries or comments, so that the skill remains in use (Chapter 28 treats the craft side of this).
- Oversight quality, in aggregate. Time to approve against diff size, share of approvals within seconds, and seeded catch rate are reported by team and never per named developer, because they are measures of the review system. Whether such measures are permitted at all is a matter for the works council or union, and Chapter 22 treats the agreements.
AI as reviewer
An AI reviewer is a system that reads a diff and writes comments on it. It is attractive because it is fast and can be applied to every change.
What is documented about its use is largely from the organisations that built it. Vijayvergiya and colleagues describe AutoCommenter at Google, which checks coding best practices in code review for C++, Java, Python and Go and, according to the authors, was deployed to tens of thousands of developers, and conclude that such a system is feasible and has a positive impact on developer workflow (196, Vijayvergiya et al., 2024). The authors are the system's builders, and the evidence reported is the authors' own evaluation. The scope also matters: the system enforces best practices that the organisation had already written down, which is the standards purpose of review, the one that can be stated as a rule. Among the sources verified for this book there is no independent field study of AI reviewers that measures defects caught against defects missed in production code; that is a gap in the evidence, and the chapter treats it as one.
From what is known, three limits are architectural, not matters of model quality.
- Correlated blind spots. An AI reviewer looking at AI-generated code may share its blind spots, especially when the two come from the same family or were trained on similar data. The concern of AI Operations, Chapter 17, about a model checking a model applies (170, Nordqvist, 2026). The partial remedy is the same: use a different mechanism where one exists (a rule, a test, a property) and measure the AI reviewer with seeded defects before relying on it.
- Unseen context. A reviewer, human or AI, sees the diff and what is attached to it. It does not see the contract a downstream system relies on, the incident of two years ago that explains an odd guard, or the intent in the product owner's head. This is why the specification record matters to review, and why Chapter 5 places the intent in a record.
- Comments that look like approval. A reviewer's comment gives the impression that a review has taken place. When the AI comment says nothing is wrong, the human reviewer is invited to agree. Both organisations in this book therefore write the rule into the delegation profile: no AI review comment counts as a human review.
An AI reviewer is a useful additional check when it is evaluated like one. Run it on a sample with seeded defects and a sample of changes whose outcomes in production are known. Record its precision, meaning the share of its comments that a developer judged correct and useful, and its recall on the seeded set. Report both with the date and the model version, and treat a change of model version as the end of the evidence, because a provider's model update changes the instrument (Chapter 20 gives the evidence-age rules). Use it for conventions, obvious defects and summaries, and keep a person as the one who reads for intent, design and security-critical logic.
Evaluating AI output more generally
The same discipline applies when an organisation evaluates a coding model or tool before adoption. Acceptance rate measures what developers accept, not whether the accepted code is right or stays; pass rates on public benchmarks depend on the strength of the benchmark's tests (193, Liu et al., 2023). An evaluation that supports a decision uses tasks from the organisation's own codebase, an oracle written by people who did not see the model's output, held-out cases that nobody tuned prompts against, a stated number of runs because outputs vary, and a record of the model and tool version. Chapter 20 takes the measurement of adoption further; Chapter 10 treats security evaluation, including the studies of Pearce and colleagues (228, Pearce et al., 2021) and the vendor report of Veracode (229, Veracode, 2025).
A verification plan and a review record
The two artefacts below show the practice at Hansa Mutual. The verification plan VER-HM-2030-0007 covers a change to the deductible and cap calculation in the claims core SVC-HM-001, drafted with the Mode 3 agentic tool in the claims core delivery team of Stefan Brückner. The record is illustrative; the identifiers follow the profile in docs/EXAMPLE_ORGANISATIONS.md.
verification_plan:
  id: VER-HM-2030-0007
  change: CHG-HM-2030-0412
  service: SVC-HM-001
  summary: Deductible and cap calculation for property claims, rule version 14
  generator:
    kind: agent
    mandate: MND-HM-DEV-02
    run_record: RUN-HM-2030-0188
    delegation: DLG-HM-DEV-01          # generate: Level 2 Supervised outside payment path
  security_or_payment_path: true        # payout amounts: Level 1 Assisted, named reviewer required
  spec: SPC-HM-2030-0031                # derived from the policy wording, version 2030-09
  oracle:
    owner: Ewelina Maj                   # test engineer, not the author of the change
    sources:
      - policy_wording_examples        # 36 cases written by claims experts
      - properties_from_wording        # payout >= 0; payout <= sum_insured; monotonic in loss
      - replay_last_quarter            # differential check on 12,400 recorded claims
    drafted_by_assistant: HM-DEV-002    # drafts only; oracle approved by the owner above
    generator_can_edit: false
  mutation:
    scope: changed_lines
    minimum_score: 0.80                 # starting value set by the quality function; not a benchmark
    may_lower: quality_function_only
  static_analysis: platform_ruleset_v9
  review:
    approvals_required: 2               # human approvals; an AI comment never counts
    reviewer_reads_first: [SPC-HM-2030-0031, VER-HM-2030-0007]
    seeded_defect_sample: true
  steward:
    name: Stefan Brückner
    revert: pipeline_rollback_and_feature_flag
    revert_authority_outside_pipeline: Hansa Forge on-call lead
  valid_until: 2031-01-31               # evidence expires with the rule version
The review record written at merge states what actually happened, including what the plan did not cover.
review_record:
  id: RVW-HM-2030-0412
  verification_plan: VER-HM-2030-0007
  merged: 2030-10-21
  reviewers:
    - { name: Dr. Marit Sommer, role: ROLE-HM-DEV-01, read_before_ai_comments: true, minutes: 55 }
    - { name: Tomasz Kowal,     role: ROLE-HM-DEV-01, read_before_ai_comments: true, minutes: 20 }
  ai_review_comments: { posted: 9, judged_useful: 4, judged_wrong: 2, noise: 3 }
  checks:
    static_analysis: passed
    properties: { run: 3, passed: 3, failing_case_found_and_fixed: 1 }
    replay_last_quarter: { claims: 12400, differences: 17, explained: 17 }
    mutation_score: { reached: 0.83, live_mutants_reviewed: 22, tests_added: 5 }
  not_covered: [partial-loss claims with two deductibles, tracked as FND-HM-2030-0021]
  human_explanation_without_tool: passed   # steward restated the rule from the wording
  outcome: merged
In the records, a test engineer wrote the oracle from the policy wording and recorded claims, and HM-DEV-002 drafted test code without power to alter it. The AI review comments were counted and graded, and did not count as one of the two human approvals. The record states what was not covered, because a record that lists only passes invites the reading that everything was tested.
Nordvik Region and Hansa Mutual
Nordvik Region
The Region's practice before this year was one reviewer from the same team and no rule about generated code (docs/EXAMPLE_ORGANISATIONS.md). DLG-NR-DEV-01 (AIDR-1101) sets review at Level 0 Advisory, so no AI review comment counts as the human review, and test at Level 1 Assisted for test drafts, never the oracle for the same change. The case platform team, working with the quality function, adds a rule for citizen-facing changes in the portal SVC-NR-002 and the benefits workflow: a second reviewer from outside the author's team, and an oracle approved by the quality engineer. The rationale is the Region's public-law setting. A defect in a benefits workflow reaches a resident, and the authority has to be able to give reasons for decisions the software supports, so a reviewer's reading of the change is part of the record the Region may be asked to produce. The capacity is limited: 18 developers, four testers, and 31 per cent of the 96 repositories with an owner who has left or moved (OWN-NR-2030-00). A rule that asks for a second reviewer from another team is therefore also a rule that reveals which repositories have no one who can review them.
The person who asks the right question is Saga Edvardsson, the quality engineer who owns the portal's regression pack: who writes the oracle? In the answer proposed here she approves the oracle for each citizen-facing change, the tech lead Anders Falk records the choice of layers in the plan, and the Mode 2 pilot NR-DEV-001 may draft tests that she reads but may not alter the regression pack. The regression pack covers the portal and the benefits workflow only, so for the inherited case systems the plan records that there is no independent oracle and that the change therefore stays at Level 0 Advisory for any tool, with a second reviewer who knows the system. No study cited here measures what that rule costs in lead time, and the Region should measure it before extending the rule (Chapter 20).
Hansa Mutual
Hansa Mutual's profile already holds the elements, and the work is to make them one practice. DLG-HM-DEV-01 (AIDR-1153) sets review at Level 1 Assisted, never counting an AI comment as one of the two required approvals; sets test at Level 1 Assisted for drafts by HM-DEV-002 (AIDR-1152), with the oracle for a change written by someone other than its author; and keeps generation inside the security-critical and payment paths at Level 1 Assisted. The group adds mutation testing on claims calculations, as in VER-HM-2030-0007, and a seeded-defect sample run by the quality function.
The weakness the profile records is not an AI weakness. In the COBOL estate the second approver is often the author's only colleague. The duplicated settlements of June 2029 (INC-HM-2029-0207), in which one reviewer who was also the only other person who knew the module approved a change that paid 312 claims twice, show what a review without independence looks like when nobody used AI at all. The review passed because the reviewer and the author shared the same knowledge and the same gaps. For this estate the independent oracle is a replay of recorded settlement runs and an expert's cases, written by Ewelina Maj's test automation team in the Polish service centre. The legacy-code explainer HM-DEV-003 stays at Level 0 Advisory in its pilot, and its explanation of a COBOL module is not an oracle. It is another reader of the same code, to be checked against the recorded runs. Representation shapes how the review measures are used. Under the draft annex KBV-IT-2024-DEV-01, telemetry from coding tools is reported by team and never per named developer, with a minimum group size of five, and the Konzernbetriebsrat co-determines under BetrVG §87(1) no. 6 on measures suited to monitor behaviour or performance. The oversight-quality figures above are reported on that basis, and Chapter 22 treats it.
Across the usage modes
The table gives the highest degree of delegation for each mode that the two organisations allow for the proving of a change, with the condition. It reports what the profiles allow; it is not a recommendation for other organisations, whose ceilings are set by their own evidence.
| Usage mode | What it does in proving | Highest degree allowed here | Condition |
|---|---|---|---|
| Mode 0 Ambient AI | Inline lint hints and completion of test boilerplate in the IDE | Level 1 Assisted | The developer reads what is inserted; not a check |
| Mode 1 Conversational assistant | Explains a failing test, suggests cases to consider | Level 0 Advisory | Output is a prompt for the developer's own thinking; no code with special-category data or credentials |
| Mode 2 Embedded assistant | Drafts tests and review summaries in the IDE or the pull request | Level 1 Assisted | Oracle written or approved by a person other than the author; AI comment never counts as review |
| Mode 3 Agentic work tools | Opens pull requests with tests and runs the suite in a sandbox | Level 2 Supervised outside security-critical and payment paths; Level 1 inside them (Hansa) | Cannot edit oracle, review rules or gates; two human approvals; named steward |
| Mode 4 AI application | A test-drafting assistant (HM-DEV-002); an AI reviewer service would sit here |
Level 1 Assisted | Measured with seeded defects; version and date recorded; evidence expires on model change |
| Mode 5 Autonomous production agents | None used for proving or merging | Not allowed | Level 4 is never used for a change to production without a gate the change cannot alter, nor for review of security-critical code without a named human reviewer |
The prohibitions of the delegation ladder that bear on proving are these: Level 4 Autonomous is never used for code in a security-critical or safety-critical path without human review by a named developer, for a change to the agent's own test oracles, review rules or pipeline gates, or for a change to production without a gate that the change itself cannot alter. A patch-level dependency update at Hansa Mutual (MND-HM-DEV-01, Level 3 Bounded) is permitted because the oracle is the existing suite, the agent cannot edit it, the update is on an approved list and a human approved the class.
Stewardship applies wherever AI took part in a change that reaches production: Name is passed when the plan and the record name the steward and reviewers, Understand when the steward can restate the rule from the specification without the tool, and Revert when the plan names a rollback that works outside the pipeline that shipped the change.
Observable, expected, speculation
Observable. Review delivers knowledge transfer and standards enforcement alongside defect finding (190, Bacchelli & Bird, 2013). Test strength changes the measured correctness of generated code (193, Liu et al., 2023). Mutation-guided test generation is in use at Meta (195, Foster et al., 2025), an AI review-comment system has been deployed to tens of thousands of developers at Google, as reported by its builders (196, Vijayvergiya et al., 2024), and surveys link AI adoption with lower delivery stability (42, Harvey & DeBellis, 2025).
Expected. Mutation score and an independent oracle as conditions of merge for generated code in important paths are expected to spread, on the basis of the stability findings and of texts that already require testing and source code review before deployment (15, European Commission, 2024). Review capacity is expected to become an explicit limit on merge rate in teams that use agents.
Speculation. Machine-verified correctness of whole enterprise systems, and AI reviewers that reliably find the defects humans miss, are speculation: no verified study in this book's sources measures either. The author's own projections are kept to Chapters 29 and 33.
Summary
This chapter treated D4 Prove. Review is a mixed instrument that finds some defects, spreads knowledge and enforces conventions, and its value for the stewardship principle is that it creates a second person who can explain the change. Testing is a set of layers, each answering a different question, and the strength of any pass is the strength of the oracle behind it. The corollary of the stewardship principle, that the test oracle must be independent of the generator, was turned into three rules: authorship, source and protection. Independence is shown by seeded defects and held-out cases, not asserted.
The volume problem is arithmetic as well as psychology. When generation is cheap, review capacity bounds the merge rate, and the choice is between a visible cap and an invisible thinning. The design measures are size limits, description before diff, budgets, queue caps, seeded defects, rotation and oversight-quality figures reported in aggregate and agreed with staff representatives. An AI reviewer is a useful additional check when evaluated like one and never counts as the human review.
For D3 Build, the lesson is that a generator is only as trustworthy as the checks it cannot edit. For D5 Steward, a verification plan and a review record are the evidence that the Name, Understand and Revert tests were passed, and they expire with the rule version and the model. In the two organisations, Nordvik Region adds a second reviewer and an approved oracle for citizen-facing change and learns from it which repositories have no one to review them; Hansa Mutual joins mutation testing, a protected oracle and seeded defects into one plan and sees in the duplicated settlements that independence was missing before AI arrived. Chapter 10 turns to the part of proving that concerns security, supply chain and the toolchain as an attack surface.
Sources
- Bacchelli, A. & Bird, C. (2013). Expectations, Outcomes, and Challenges of Modern Code Review. ICSE 2013, pp. 712-721. DOI: 10.1109/ICSE.2013.6606617. (190, Bacchelli & Bird, 2013)
- Sadowski, C., Söderberg, E., Church, L., Sipko, M. & Bacchelli, A. (2018). Modern Code Review: A Case Study at Google. ICSE-SEIP 2018, pp. 181-190. DOI: 10.1145/3183519.3183525. (191, Sadowski et al., 2018)
- Czerwonka, J., Greiler, M. & Tilford, J. (2015). Code Reviews Do Not Find Bugs: How the Current Code Review Best Practice Slows Us Down. ICSE 2015, volume 2, pp. 27-28. DOI: 10.1109/ICSE.2015.131. (192, Czerwonka et al., 2015)
- European Commission (2024). Commission Delegated Regulation (EU) 2024/1774 supplementing Regulation (EU) 2022/2554 with regard to regulatory technical standards specifying ICT risk management tools, methods, processes, and policies and the simplified ICT risk management framework. Article 16. (15, European Commission, 2024)
- Souppaya, M., Scarfone, K. & Dodson, D. (2022). Secure Software Development Framework (SSDF) Version 1.1. NIST SP 800-218. (232, Souppaya et al., 2022)
- European Parliament and Council of the European Union. Regulation (EU) 2024/1689 laying down harmonised rules on artificial intelligence (Artificial Intelligence Act). Article 14(4)(b). (1, European Union, 2024)
- Nordqvist, G. (2025). Architecture as Code. The Architecture as Code Series, Book 1, published at aac.geon.se. (161, Nordqvist, 2025)
- Claessen, K. & Hughes, J. (2000). QuickCheck: A Lightweight Tool for Random Testing of Haskell Programs. ICFP '00, pp. 268-279. (199, Claessen & Hughes, 2000)
- Petrović, G., Ivanković, M., Fraser, G. & Just, R. (2021). Does Mutation Testing Improve Testing Practices? ICSE 2021, pp. 910-921. (194, Petrović et al., 2021)
- Foster, C. et al. (2025). Mutation-Guided LLM-based Test Generation at Meta. arXiv:2501.12862. (195, Foster et al., 2025)
- Sadowski, C., Aftandilian, E., Eagle, A., Miller-Cushon, L. & Jaspan, C. (2018). Lessons from Building Static Analysis Tools at Google. Communications of the ACM 61(4), 58-66. (197, Sadowski et al., 2018)
- Newcombe, C. et al. (2015). How Amazon Web Services Uses Formal Methods. Communications of the ACM 58(4), 66-73. (198, Newcombe et al., 2015)
- Barr, E. T., Harman, M., McMinn, P., Shahbaz, M. & Yoo, S. (2015). The Oracle Problem in Software Testing: A Survey. IEEE Transactions on Software Engineering 41(5), 507-525. (178, Barr et al., 2015)
- Liu, J., Xia, C. S., Wang, Y. & Zhang, L. (2023). Is Your Code Generated by ChatGPT Really Correct? arXiv:2305.01210. (193, Liu et al., 2023)
- Nordqvist, G. (2026). AI Purple: How Red and Blue Learn Together When AI Joins the Loop in European Enterprises and Public Authorities. The Architecture as Code Series, Book 9, published at aipurple.geon.se. (169, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Operations: How Artificial Intelligence Transforms IT Operations in European Enterprises and Public Authorities. The Architecture as Code Series, Book 10, published at aiops.geon.se. (170, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Governance: Governing Artificial Intelligence in European Enterprises and Public Authorities. The Architecture as Code Series, Book 2, published at aig.geon.se. (162, Nordqvist, 2026)
- Stack Overflow (2025). 2025 Stack Overflow Developer Survey. (217, Stack Overflow, 2025)
- Google Cloud, DORA (2024). Accelerate State of DevOps Report 2024. (216, Google Cloud, 2024)
- Harvey, N. & DeBellis, D. (2025). Announcing the 2025 DORA report: State of AI-assisted Software Development. (42, Harvey & DeBellis, 2025)
- Perry, N., Srivastava, M., Kumar, D. & Boneh, D. (2023). Do Users Write More Insecure Code with AI Assistants? CCS '23, pp. 2785-2799. (34, Perry et al., 2023)
- Goddard, K., Roudsari, A. & Wyatt, J. C. (2012). Automation bias: a systematic review of frequency, effect mediators, and mitigators. JAMIA 19(1), 121-127. (43, Goddard et al., 2012)
- Becker, J., Rush, N., Barnes, E. & Rein, D. (2025). Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity. arXiv:2507.09089. (63, Becker et al., 2025)
- Nordqvist, G. (2026). AI Leader: How Leadership Roles Change When AI Is Used Broadly in European Enterprises and Public Authorities. The Architecture as Code Series, Book 11, published at leader.geon.se. (174, Nordqvist, 2026)
- Nordqvist, G. (2026). The Transformed Security Architect: Role, Craft and Career in the Age of AI in European Enterprises and Public Authorities. The Architecture as Code Series, Book 6, published at tsa.geon.se. (166, Nordqvist, 2026)
- Vijayvergiya, M. et al. (2024). AI-Assisted Assessment of Coding Practices in Modern Code Review. arXiv:2405.13565. (196, Vijayvergiya et al., 2024)
- Veracode (2025). October 2025 Update: GenAI Code Security Report. (229, Veracode, 2025)
- Pearce, H., Ahmad, B., Tan, B., Dolan-Gavitt, B. & Karri, R. (2021). Asleep at the Keyboard? Assessing the Security of GitHub Copilot's Code Contributions. arXiv:2108.09293. (228, Pearce et al., 2021)