Measuring and Leading AI Adoption in Development
Most development organisations that have bought AI coding tools can say how many seats they hold, and many can show an acceptance rate from the tool's own dashboard. Few can say what changed in the delivery of software as a result, for which work, and how they know. This chapter concerns D3 Build and D5 Steward. D3 Build is where the tools are used, in the editor, the pull request and the agent's run. D5 Steward is where the consequences land, in release, maintenance, incidents and the ownership of what was built. A claim about adoption in development is the place where the two meet: it is made about how code is written, and it is paid for in what has to be reviewed, tested, operated and reverted afterwards. The measures also depend on the other three functions, because the specification of D1 Frame and the independent oracle of D4 Prove are what make an outcome measurable at all.
The chapter argues that an adoption programme in development is led by treating every claim about adoption, productivity and quality as a claim in the sense of the series: it has a scope, a method, a date, a result and an expiry. It sets out how a programme is organised, what the established metric frameworks measure, why acceptance rate and lines of code mislead, what the productivity J-curve implies, how to run and stop an experiment, and what an adoption and value record looks like. The debate on whether AI makes developers more productive follows in four steps, and a verdict separates what is observable from what is expected and what is speculation.
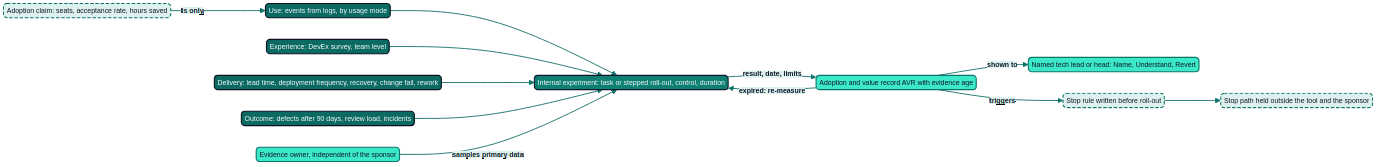
Figure 20.1: From adoption claim to evidence: the four measure families, the internal experiment, the adoption and value record, and the stop rule with a stop path outside the tool and the sponsor.
What the earlier volumes settle
The conclusions of the earlier volumes that carry this chapter are summarised so that it stands alone.
AI Leader, Chapter 20, treated adoption in general: a claim about adoption, productivity or competence carries scope, method, date, result and expiry, and is shown as verified, expired or asserted, with default clocks of 90 days for usage and 180 days for value chosen by convention. The adoption and value record keeps the quoted and the measured figure side by side, says "not measured" where that is true, and names an evidence owner independent of the sponsor; a programme has a stop rule written before the roll-out (174, Nordqvist, 2026). This chapter reuses that form for development and calls the record AVR-*. AI Operations, Chapter 20, set out what the key metrics of the DevOps Research and Assessment (DORA) programme (four in the 2014-2023 formulation, five in the current guide) show and where they mislead: they describe a service and not a person, and they can be gamed when they become targets (170, Nordqvist, 2026). In this book "DORA" otherwise means Regulation (EU) 2022/2554.
AI Purple, Chapter 18, found that counts of activity, which AI makes cheap to raise, are poor measures of a loop, that Goodhart's law applies in several forms and that measures describe a system, are reported for a team and not a named person, and are agreed with employee representatives first (169, Nordqvist, 2026) (61, Manheim & Garrabrant, 2019). AI Boss, Chapters 13 and 15, found the evidence on algorithmic management mixed (167, Nordqvist, 2026); developer telemetry is treated in Chapter 22, and here only what measurement needs is said. AI Governance, Chapter 22, gave the three labels used throughout: observable, expected and speculation (162, Nordqvist, 2026). The author's own projections are kept to Chapters 29 and 33.
The stewardship principle of Chapter 4 adds one rule: a change made inside an experiment has a named owner who passes the tests Name, Understand and Revert, and the experiment does not lower the bar a change must pass, in either arm.
Adoption is a programme with a portfolio
An adoption programme that consists of buying seats and reporting how many were activated has no way to fail. The programme a tech lead or head of development can lead has a portfolio of use cases, each with a sponsor, a hypothesis and a stop rule.
A use case in development is a class of work that an AI system supports or performs within a usage mode and at a degree of delegation, drawn from the classes of Chapter 4 (specify, design, generate, refactor, test, review, deploy, operate, document, migrate). "Generate at Level 1 Assisted in the IDE" and "refactor at Level 2 Supervised through an agent that opens pull requests" have different risks, costs and evidence, and reporting them as one adoption percentage describes neither. A sponsor is the named person who owns the outcome the use case should change, such as the tech lead whose review queue should shorten, and not the person who bought the licence. A hypothesis states what should change, for whom and by how much, and what would show that it did not. A stop rule states the date and condition at which the use case is paused or ended.
Four consequences follow. A seat is an input, not an outcome: it says how much was spent. Enablement is part of the programme and its cost: the time developers spend learning to direct a tool, to read generated code critically and to write the specification that makes generation checkable is an investment, and the programme records it. The programme needs an owner of the evidence who is not the owner of the success; when the sponsor also produces the dashboard the programme has the structure that AI Purple called a loop closed by one side, and the evidence owner is often the controller, the quality function or the platform team's data function, never the vendor and never the sponsor. And the portfolio is a resource decision taken by people: an assistant can draft the overview and rank use cases, but it does not allocate the budget or extend its own mandate, since a change to an agent's own mandate, permissions, test oracles or pipeline gates is barred at Level 4 Autonomous (Chapter 4).
What the metric frameworks measure
Three frameworks dominate the discussion of developer productivity, and each answers a different question. A programme that knows what each was built to answer can use them together and avoid asking one of them for what it cannot give.
The software delivery metrics of the DORA programme
The DevOps Research and Assessment programme measures the performance of software delivery. The programme's guide groups its metrics into throughput (change lead time, deployment frequency and failed deployment recovery time) and instability (change fail rate and deployment rework rate), so that the guide lists five metrics where the key metrics of earlier years listed four (222, Harvey, 2026). The guide also states three conditions that matter for an adoption programme. The metrics are best suited to measuring one application or service at a time, and blending them across teams or comparing very different applications can mislead. The aim is improvement over time and not competition between teams or organisations. And setting the metrics as goals increases the likelihood that teams will try to game them (222, Harvey, 2026).
The two groups are read together: a tool that raises the number of changes shipped while raising the share that fail or need rework has moved one group and harmed the other. The programme's own surveys illustrate this. Its 2024 report found that as AI adoption increased it was accompanied by an estimated decrease in delivery throughput of 1.5 per cent and an estimated reduction in delivery stability of 7.2 per cent (221, Google Cloud, 2024). The 2025 report, from nearly 5,000 technology professionals, found a positive relationship between AI adoption and throughput and product performance and a continuing negative relationship with stability (42, Harvey & DeBellis, 2025). Both are survey associations from a programme hosted by a cloud provider and neither is a controlled comparison; they show which two groups of measure to look at, and that they can move in opposite directions.
SPACE and DevEx
The SPACE framework argues that developer productivity is multidimensional, covering satisfaction and well-being, performance, activity, communication and collaboration, and efficiency and flow, and that no single metric stands for it (62, Forsgren et al., 2021). A programme that reports one number, such as weekly active users or hours saved, reports one dimension of five. The developer experience framework of Noda, Storey, Forsgren and Greiler names three dimensions, feedback loops, cognitive load and flow state, and proposes to measure them by combining developers' perceptions with data from the systems they work in (227, Noda et al., 2023). The contribution for an adoption programme is the pairing: a survey says how the work feels, workflow data says how long review, build and rework take, and where the two disagree the disagreement is the finding.
Four families of measure
The three frameworks combine into four families that an adoption programme in development reports side by side. The grouping is the book's own, drawn from the frameworks above.
| Family | Example measures | What it can show | Where it misleads |
|---|---|---|---|
| Use | Active seats, feature events by usage mode, share of work classes touched | Reach and willingness to try | Value, quality, or who reviewed the output |
| Experience | Team-level survey on feedback loops, cognitive load, flow; time to first review | How the work feels and where friction sits | Delivery outcomes; perceived and measured effects can diverge |
| Delivery | Change lead time, deployment frequency, failed deployment recovery time, change fail rate, deployment rework rate, per service | Whether delivery of one service got faster or less stable | Individual output; any comparison between teams of different services |
| Outcome | Defects and incidents traceable to changes after 30 and 90 days, review load per change, share of generated code that persists | Whether what shipped stayed shipped | Short periods; changes whose owner cannot be named |
Each measure carries a gaming check, a second measure that does not use the same data and would move if the first were being gamed. Change lead time is checked against change fail rate, and the share of generated code merged is checked against the share of it that persists.
Why acceptance rate and lines of code mislead
The acceptance rate of an assistant is the share of shown suggestions that the developer accepts. It is cheap to compute, it is in the vendor's dashboard and it is easy to mistake for value. It is an activity measure at Mode 2, and it has three weaknesses.
First, it measures a reaction to a suggestion and not the fate of the code. In a study of users of a code-completion product, Ziegler and colleagues reported that the rate at which shown suggestions were accepted was what drove developers' perception of productivity, and that measures of how long completions persisted in the code did not play that role (210, Ziegler et al., 2022). The study concerns perceived productivity; it does not show that an accepted suggestion is a good one.
Second, its level depends on the configuration. Provider models change under the same product name, as AI Leader, Chapter 20, recorded for adoption figures in general (174, Nordqvist, 2026), so an acceptance rate is a property of the tool and the codebase together, valid for one configuration and one date. Third, it becomes a target, and Goodhart's law then applies in its variants (61, Manheim & Garrabrant, 2019). A published example of a share of generated code is the statement of Alphabet's chief executive in October 2024 that more than a quarter of all new code at Google was generated by AI and then reviewed and accepted by engineers (45, Pichai, 2024). It is an observable report from a company on its own code; it does not say how "new code" is counted, how much survived review or what happened to defects, and quoted elsewhere without its definition it becomes a slogan.
Lines of code count output and not the need it answers; more generated lines can mean more to review, maintain and revert. A count of completed tasks or pull requests is a useful proxy inside one organisation, as in the field experiments of Cui and colleagues (176, Cui et al., 2024), but the scope of a pull request is shaped by organisational norms, which is the book's own observation, and the count should not be read across organisations.
Both organisations in this book hold a claim of this kind, an activity count or a perception reported as an outcome with no evidence age: Hansa Mutual's "42 per cent AI-assisted" and Nordvik Region's "a third faster" (AVR-HM-2030-01, AVR-NR-2030-01; both are taken up at the end of the chapter).
The productivity J-curve
Brynjolfsson, Rock and Syverson show why a technology that raised nothing in its first years is not worthless, and why one that raised everything calls for the question of what was counted. General purpose technologies enable and require significant complementary investments in processes, products, business models and human capital, which are often intangible and poorly measured; in their model productivity growth is underestimated in a technology's early years and overestimated later, when the intangible investments are harvested, which they call the Productivity J-curve (52, Brynjolfsson et al., 2021). It is a macroeconomic model estimated on national data and says nothing about any one development organisation's curve.
For a development organisation three implications follow, and they are the book's own conclusions. The first is that the early period of a programme has a cost side that does not appear in a time-saved figure: writing and testing the specifications that make generation checkable (Chapter 5), building the independent test oracle (Chapter 9), enlarging review capacity for a higher volume of changes (Chapter 9), setting mandates and sandboxes for agents (Chapter 8) and enabling the developers. The record therefore carries an investment ledger and a return ledger, and the board sees both. The second is that the curve is no reason to wait for a payoff on faith. The same model implies that later figures can overstate the effect, and a leader with an investment ledger can tell a failing use case from one that is still paying for its set-up. The third concerns labels. That any particular organisation will reach a payoff within a stated time is speculation. The Danish administrative data, in which two years after the launch of ChatGPT earnings and recorded hours had not moved although adoption and perceived benefit were widespread, are observable evidence at the level of occupations, and they concern no developers in particular (53, Humlum & Vestergaard, 2025).
Experiments inside the organisation
Published averages describe other people's codebases, and the effect depends on the task, the person and the conditions, so the only study that tells an organisation whether a tool helps in its own work is one run in it. It needs a comparison, a period long enough for the outcome to appear, outcome data from primary records and a plan for the result before it is known.
The comparison
Three designs suit a development organisation. A task-level comparison assigns each eligible task, by a recorded coin flip at planning, to AI allowed or AI not allowed, within the same developers and sprint; it is the design of the randomised study described below, and its weakness is that developers can change what they put forward. A stepped roll-out enables the tool for one team after another in randomised order, the teams not yet enabled serving as controls; it suits an organisation with many teams, such as Hansa Mutual's 62 delivery teams, and measures the delivery metrics at service level as the DORA guide asks. A before-and-after comparison within one team is the weakest and cheapest design, and the only one open to the smallest team; it cannot separate the tool from the sprint, the season, the staffing or a model update, and its result is stated with that limit.
What the studies teach about design
The published trials show what goes wrong. The randomised study of Becker and colleagues, with 16 experienced developers and 246 tasks, is described in the debate below; its authors say that experimental artefacts cannot be entirely ruled out (63, Becker et al., 2025). METR, the group that ran it, published a changed design on 24 February 2026. A new experiment from August 2025 had 57 experienced contributors (ten returning, 47 new), more than 800 tasks and 143 repositories, with tasks pre-specified by the developers and then randomised. The estimates were an 18 per cent reduction in time for returning developers (interval from 38 per cent less to 9 per cent more) and a 4 per cent reduction for new developers (15 per cent less to 9 per cent more). The group calls this an unreliable signal, mainly because developers declined to take part, or withheld tasks, because they did not want to work without AI; in surveys 30 to 50 per cent said they had withheld some tasks. It believes the bias runs downward, that developers are likely more sped up in early 2026 than in early 2025, and that the data are only very weak evidence for the size of the increase (186, METR, 2026).
Three lessons follow, and they are interpretations. Selection is a result as well as a threat: if developers will not take part without the tool, the organisation has learned something about reliance that Chapter 28 takes up, and the experiment records the refusals. Time logged by developers who run several agents at once is unreliable, so outcome measures come from the pipeline and not from self-reports. And a result expires when the tool, the model or the developers' skill in directing it changes.
Duration, outcome and denominator
The outcome fixes the period. Change lead time and review time appear within a sprint; defects and incidents attributable to a change appear after weeks or months. An experiment that decides at the end of a pilot reports the fast measures and records the slow ones as pending, with the date they will be read. The denominator includes tasks withheld, developers who did not take part and changes that were reverted; a result that cannot say how many are missing is asserted.
Practical guide: run an internal experiment on an AI coding tool
Purpose. To replace a perceived effect with a measured one for one use case in one codebase, with the limits stated.
Roles. The sponsor (a tech lead or head of development); an evidence owner independent of the sponsor (controller, quality function or the platform team's data function); the developers who take part; the engineer who holds the pipeline data; the employee representatives, who agree the counting rule beforehand; the data protection officer; in a public authority the archivist, where prompts and outputs may be public records.
Inputs. The claim as quoted; the delegation profile in force; primary data (pipeline, repository, review and incident records); the counting rule; the previous record, if any.
Steps.
- Write the claim in one sentence, name who quotes it and state its evidence age.
- Write the scope: work class, usage mode, service or repository, period.
- Choose the design, state what it cannot control for and the smallest effect it can resolve. With few developers and few sprints only a large effect can be resolved, and "not distinguishable from no effect" is a legitimate result.
- Agree the counting rule with the representatives before data are collected: no figure for a named developer, and a minimum group size below which a team is not reported.
- Fix the outcomes in the four families, each with its gaming check and the date it will be read, and include the investment ledger: hours of enablement, specification and review.
- Keep the oracle independent. Tests and review are not written by the tool that generated the change, the reviewer is not told the condition where that is practicable, and neither the agent nor a developer changes the oracle, the review rule or the pipeline gate during the experiment.
- Record refusals and withheld tasks, and read the fast measures on the planned date.
- File the quoted and the measured figure side by side, say what is pending and set the expiry.
- Decide against the stop rule fixed in advance, and file an AI Decision Record if the result changes a decision.
Result. An adoption and value record (AVR-*) with the measured and the quoted figure side by side.
Stopping what does not work
An adoption programme without a stop rule has the structure of a ratchet: licences are bought on annual terms, sponsors have reputations, and a tool that developers like is hard to withdraw. Three rules are written before the roll-out.
A stop condition tied to evidence, not to mood. A condition for use is a share at expiry below which roll-out to new teams pauses. A condition for value is a margin on a measured outcome after a stated period, for example that a service's change fail rate has not risen by more than a stated amount while its change lead time has not fallen. The numbers are fixed beforehand, which is what makes the rule a rule. Developers who felt faster were slower in the randomised study described above, so "the developers want to keep it" is neither a stop condition nor a continue condition.
A stop path outside the tool. Pausing a use case depends neither on the assistant being paused nor on the sponsor who wants it to continue. The licence, the gateway route and the repository permissions are held by a named office, such as the platform team, that does not report to the sponsor, as AI Operations made the rule for operations agents (170, Nordqvist, 2026); for a coding agent with a mandate the stop path is exercised and not assumed (Chapter 8). For a service supporting an important function of a financial entity, DORA Article 28(3) puts the contractual arrangement on the register of information and Article 28(8) asks for an exit strategy, which is where the stop path and the exit are written down (2, European Union, 2022).
A way to stop part of it. A use case can help in one work class and harm in another. In the consulting experiment of Dell'Acqua and colleagues, participants completed 12.2 per cent more tasks and 25.1 per cent faster on tasks inside the model's frontier and were 19 percentage points less likely to produce the correct solution on a task outside it (81, Dell'Acqua et al., 2023). The finding concerns consultants, and it makes the developer trials' point: the unit of decision is the work class. Stopping is a decision for people; an assistant can prepare the evidence, and if the stop changes the work of staff the consultation that applies in the organisation applies (Chapter 22).
An adoption and value record
The record is a short versioned file kept beside the other records of the programme, which makes it diffable and reviewable. The example is Nordvik Region's record for the pilot of the IDE assistant NR-DEV-001 as it stands at the start of the year, with the measurement plan that the retrospective decision AIDR-1102 requires before the pilot is extended. It is illustrative and agrees with the organisation's profile.
record: AVR-NR-2030-01
revision: 2
as_of: 2030-09-16
use_case: ide-assistant-pilot NR-DEV-001
usage_mode: "Mode 2 Embedded workplace assistants"
work_classes: {generate: "Level 1 Assisted", test: "Level 1 Assisted"}
sponsor: Gunilla Roos            # head of Applications and Integration
claim_owner: Anders Falk         # tech lead, wrote the April 2030 note
evidence_owner: regional-controlling   # independent of the sponsor
claim:
  quoted_value: "a third faster"
  quoted_date: 2030-04
  basis:
    acceptance_rate_pct: 31      # IDE telemetry, 12 developers
    survey: "9 of 12 answered: about four hours saved a week"
  delivery_time_measured: false
state:
  usage: expired                 # older than the 90-day clock
  value: asserted                # never checked against primary data
plan:
  design: task-level, AI allowed or not allowed by recorded coin flip
  period: six two-week sprints, 2030-10 to 2030-12
  outcomes: [change-lead-time, review-time, rework, defects-at-30-days]
  pending: [defects-at-90-days]  # read after the decision date
  oracle: tests and review by someone other than the tool; reviewer not told the condition
  resolves: "large effects only; interval to be stated"
  per_person_reporting: false    # agreed under MBA-NR-2030-03 before data collection
expiry: {usage_days: 90, value_days: 180, conditions: [model-change, tool-version-change, counting-rule-change]}
decision:
  supports: AIDR-1102            # pilot continued to 2030-12-31 only
  stop_rule: "no extension past 2030-12-31 without a filed, signed result and the negotiation under MBA-NR-2030-03"
Four features matter more than the syntax. The quoted claim and its basis are written down together, so that nobody has to reconstruct how "a third faster" arose. The state of each claim is explicit, and "asserted" is a legitimate entry. The plan names what the design cannot resolve, and the slow outcome is marked pending with the reason. And the oracle clause says who does not write the tests and who is not told the condition, which is the corollary of the stewardship principle in the measurement itself. The record is a version-controlled artefact; a change to the plan after data is collected is a new revision with its reason.
The debate: is AI making developers more productive?
The question has an answer for each study and no single answer for all of them. The debate follows the four steps of the authoring guide. Each position is stated at its strongest, what a source reports is separated from what it is taken to mean, and the section ends with something the reader can do.
The case for concern
The case rests on three observations. The first is the gap between the felt and the measured effect. In the randomised study of 16 experienced developers on mature repositories, the developers forecast a 24 per cent reduction in time, estimated afterwards that they had saved 20 per cent, and were measured at 19 per cent slower (63, Becker et al., 2025). If the feeling of being faster is unreliable, every survey of perceived hours saved is unreliable in a direction that favours the tool. The Stack Overflow survey of 2025 reports from self-selected respondents that 52 per cent agree AI tools or agents have had a positive effect on their productivity, and that 46 per cent distrust the accuracy of the tools against 33 per cent who trust it (217, Stack Overflow, 2025). Both figures describe belief.
The second is the stability signal. The DORA programme's 2024 survey associated rising AI adoption with an estimated 1.5 per cent decrease in throughput and a 7.2 per cent reduction in stability (221, Google Cloud, 2024), and the 2025 survey still found a negative relationship with stability (42, Harvey & DeBellis, 2025). The concern is that generation is cheaper than verification, so that changes arrive faster than they can be reviewed and the cost is paid after release, in work that belongs to D5 Steward and not to D3 Build.
The third is that the measures in use are the wrong ones. Acceptance rate and share of generated lines reward the cheapest thing a tool can do, and most studies that find a gain measure the speed of producing something: tasks completed, pull requests, time to a first working solution. Those who hold this position add that the juniors who gain most in some studies are those whose route to expertise runs through the tasks being automated (Chapter 13). An organisation that reports a gain without a measure of quality, review load and persistence has reported a number nobody has checked.
The case for calm
The case for calm starts from the other studies. Cui and colleagues pooled three field experiments at Microsoft, Accenture and an anonymous Fortune 100 company, with 4,867 developers, in which a random subset received a code-completion assistant. They found 26.08 per cent more completed tasks (standard error 10.3 per cent), with larger gains and higher adoption among less experienced developers; the authors had no access to the code produced and so could not assess its quality (176, Cui et al., 2024). A randomised trial with 96 Google engineers on a complex enterprise task found about a 21 per cent shorter task time with three AI features, with a wide interval and the authors' caution about internal tooling in summer 2024 (185, Paradis et al., 2024). In a controlled experiment, developers asked to implement an HTTP server in JavaScript finished 55.8 per cent faster with the assistant (175, Peng et al., 2023).
This position adds that the tools of the unfavourable study are no longer the tools in use. The group that measured the 19 per cent slowdown reported in February 2026 that developers are likely more sped up than a year earlier, that selection biases its new estimate downward, and that its data are very weak evidence for the size of the increase (186, METR, 2026). The 2025 DORA survey shows the association with throughput turning positive (42, Harvey & DeBellis, 2025). A leader who waits for certainty will wait while practice settles around them, and the response to uncertainty is a measured pilot, not a pause. The gains are largest where experience is thinnest (68, Brynjolfsson et al., 2025) (176, Cui et al., 2024), which supporters read as an argument for tools that raise the floor.
Where the positions meet
The positions disagree less on the facts than on which facts a leader should weight. The table sets out the studies both accept, with what was measured and where each stops.
| Study | Who and what | Result reported | Limits the authors or this chapter note |
|---|---|---|---|
| (63, Becker et al., 2025) | 16 experienced developers, 246 tasks in mature open-source projects, early-2025 tools | 19 per cent longer with AI allowed; forecast 24 per cent shorter, later estimate 20 per cent shorter | Small sample; one setting; experimental artefacts not ruled out |
| (186, METR, 2026) | 57 developers, 800+ tasks, 143 repositories, from August 2025 | 18 per cent less time (returning) and 4 per cent less (new), intervals including no effect | Developers refusing to work without AI; the group calls the signal unreliable |
| (176, Cui et al., 2024) | 4,867 developers in three companies, completion assistant, 2022 to 2023 | 26.08 per cent more completed tasks (standard error 10.3 per cent) | Noisy; outcome is pull requests; older tools |
| (185, Paradis et al., 2024) | 96 Google engineers, one complex task, summer 2024 | About 21 per cent shorter task time | Wide interval; internal tooling |
| (175, Peng et al., 2023) | Controlled experiment, one task | 55.8 per cent faster | One bounded task; no maintenance period |
| (221, Google Cloud, 2024) (42, Harvey & DeBellis, 2025) | Annual survey of technology professionals | Throughput association negative then positive; stability negative both years | Survey association; vendor-hosted |
Both sides accept five things. The effect depends on the task, the person, the codebase and the vintage of the tool. Perceived and measured effects can diverge in either direction. Throughput and stability are read together, and a gain in one that costs the other is not a gain. Selection corrupts experiments in which developers can opt out of the condition they dislike. And evidence has an age: a result about early-2025 tools is a result about early-2025 tools. No study in this list was run in a European public authority, on a legacy estate of the kind Nordvik Region and Hansa Mutual hold, or over several years. The positions also share a conclusion that is the book's own: the organisation's own measurement of its own work outweighs any published average.
What can be done
For developers: keep a record of the tasks you used the tool for and what you reviewed, and say when it slowed you down. A report that it did not help is a finding and not a complaint. For tech leads: choose a design from the three above, write the claim and its expiry before the experiment, keep the oracle independent of the generator in both arms, and report at team level with the denominator and what is pending. For engineering managers and heads of development: fix the stop rule before the roll-out, hold the stop path outside the sponsor's team, put the investment ledger beside the return ledger, and do not use acceptance rate, share of generated lines or pull request counts in appraisal or pay (Chapter 22). For leaders and boards: ask for the scope, method, date, result and expiry behind each adoption figure, and for stability beside throughput; a figure without these goes into a paper as "reported" and not as a finding. For employee representatives: ask that the counting rule, the minimum group size and the ban on per-person reporting are agreed before data are collected. For procurement: ask the supplier for the telemetry needed to measure outcomes and for the right to test, and treat vendor figures as claims by an interested party (Chapter 18).
Verdict
Observable. Published studies of AI coding assistants give mixed results that depend on the task, the person and the conditions. Randomised and field studies found gains in completed tasks and task time in 2022 to 2024; a randomised study of experienced developers on their own mature repositories found a slowdown in early 2025 with a large gap between the felt and the measured effect; and a 2026 follow-up from the same group could not give a reliable estimate because of selection. Surveys report high adoption and belief in productivity, and the DORA programme's two annual surveys associate AI adoption with lower stability in both years.
Expected. That boards, supervisors and auditors will ask for the method and date behind adoption claims is expected, since management bodies of financial entities already oversee ICT risk under DORA Article 5 (2, European Union, 2022) and the practice of verified, expired and asserted claims is spreading through the series. That organisations which keep an investment ledger will tell a failing use case from the cost side of a J-curve sooner is expected.
Speculation. That any given organisation will see a step change in measured delivery performance within a stated time is speculation. So is the sign of the net effect on quality and stability over several years, because no multi-year independent study of whole organisations exists in the sources this book has verified.
What people and organisations can influence is the quality of their own evidence: the design, the oracle, the denominator, the expiry and the stop rule. They cannot influence how the models change, and the record is built to show when that has happened.
Across the usage modes
The same word, "use", counts different things at different modes. The table sets out what an adoption figure counts in development, what it can mean and what it cannot show.
| Usage mode | What is usually counted | What it can mean | What it cannot show |
|---|---|---|---|
| Mode 0 Ambient AI | Completion switched on by default in the IDE | Availability | Whether anyone relied on it; Nordvik recorded the decision only after the March 2030 update (AIDR-1102) |
| Mode 1 Conversational assistants | Sessions, prompts, active users | Willingness to try | Which work classes changed; what was pasted into an unapproved assistant |
| Mode 2 Embedded workplace assistants | Acceptance rate, seats, share of lines | Use inside the editor | Value, persistence or review load; the figure is valid for one configuration and date |
| Mode 3 Agentic work tools | Runs, pull requests opened, share merged | Delegated effort | Correctness, rework and who owns the change; the agent never merges to the protected branch alone |
| Mode 4 Built AI applications | Tests drafted, tests accepted | Reach of a bounded use case such as HM-DEV-002 |
Whether the tests catch defects, since the oracle for a change is written by someone other than its author |
| Mode 5 Autonomous production agents | Actions executed within a mandate | Execution | Whether the mandate is right; no coding agent in either organisation merges or deploys on its own |
At every mode the count is a measure of activity, and a value claim needs a second measure taken from the work itself. Level 4 Autonomous is not available for a coding tool to change the metric definition, the dashboard query, the oracle or the gate that its own change must pass, and a use case at Level 3 Bounded is measured by its outcomes, such as the share of changes reverted, and not by the count of changes made.
Nordvik Region and Hansa Mutual
Nordvik Region. The pilot NR-DEV-001 of the IDE assistant covers 12 of the Region's 18 developers, started in February 2030 and reports a 31 per cent acceptance rate and about four hours saved a week from a survey answered by nine. Anders Falk, tech lead of the integration and data team, ran it and wrote the April 2030 note to the executive committee that said "a third faster". Evidence age at the start of the year is five months, so the usage claim has expired and the value claim is asserted (AVR-NR-2030-01). AIDR-1102 continued the pilot to 2030-12-31 only, and the union's IT representative, Tomas Ekblad, asked in June 2030 to negotiate before it is extended; the negotiation record MBA-NR-2030-03 is open. The duty to negotiate before an important change follows from sections 10 to 12 of the Swedish co-determination act (10, Swedish Parliament (Sveriges riksdag), 1976). The plan therefore depends on a counting rule agreed before data are collected and on a result by the end of the year.
Nordvik's size shapes the design. With 12 pilot developers and six sprints a task-level comparison can show a large effect and cannot show a small one; the study of 16 developers and 246 tasks produced an interval from 2 per cent to 39 per cent longer (186, METR, 2026). The record says so in its resolves line. The Region's teams have six to eight people, and its rule in AI Leader, Chapter 20, for figures about its staff assistant was that no team below a group size of ten is reported (174, Nordqvist, 2026); under that rule no team in Applications and Integration could be reported, so the pilot is reported as a whole and the minimum group size is a question for MBA-NR-2030-03. The evidence owner is regional controlling, not Gunilla Roos, who is accountable for DLG-NR-DEV-01, nor Anders Falk. The plan is carried into the criteria of tender NR-2030-041 so that a supplier's figures arrive with their method (Chapter 18). The model is self-hosted, so ending the pilot does not depend on a supplier; the stop path should be held by the platform team, which does not report to the sponsor, and the pilot's direct calls to the model are a gap that the gateway of Chapter 16 closes.
Hansa Mutual. The IDE assistant HM-DEV-001 has 340 licences, and its dashboard reported 42 per cent of committed lines in the claims product line as AI-assisted in February 2030. Stefan Brückner, tech lead of the claims core delivery team in Hamburg, owns the figure in his team, and the group CIO, Rainer Lehmann, reported it to the executive board. The August 2030 sample of 40 merged pull requests found 27 per cent of lines traceable to an accepted suggestion and said nothing on persistence (AVR-HM-2030-01; the 42 per cent figure is seven months old at the start of the year). The record marks the 42 per cent expired, the 27 per cent verified for that sample, and persistence and value not measured. Hansa has the scale for a stepped roll-out across the product line's delivery teams, measured at service level, with the Hansa Forge gateway under Lukas Frey holding the data and group controlling, independent of the CIO who owns DLG-HM-DEV-01, as evidence owner.
The Konzernbetriebsrat co-determines under section 87(1) no. 6 of the BetrVG on tools suited to monitor behaviour or performance (9, Germany, n.d.). The annex KBV-IT-2024-DEV-01, drafted in autumn 2030, reports coding-tool telemetry by team and never per named developer, with a minimum group of five, and rules out acceptance rates in appraisal or pay; the measurements here are drawn inside it. HM-PROC-AIDEV-2029-01 is on the register of information as a service supporting an important function, so the exit strategy of DORA Article 28(8) applies to the assistant and the stop path is written beside it. The Level 3 Bounded class of patch-level dependency updates (MND-HM-DEV-01) is the cleanest use case to measure, because its outcome shows in the pipeline: updates reverted, failed builds after merge and updates that needed a human, not updates merged.
Both organisations hold an adoption claim without evidence age that has reached a senior body. Nordvik's measured result is pending, and Hansa's measured figure is lower than its claim, with no value claim attached to either.
Summary
This chapter concerned D3 Build and D5 Steward, and the measures that depend on D1 Frame, which fixes what is to be checked, and D4 Prove, which keeps the oracle independent of the generator. An adoption programme in development treats every claim about adoption, productivity and quality as a claim with a scope, a method, a date, a result and an expiry. It has a portfolio of use cases by work class and usage mode, each with a sponsor, a hypothesis and a stop rule, and an evidence owner who is not the sponsor. A seat is an input and not an outcome.
The delivery metrics of the DORA programme, SPACE and DevEx answer different questions and combine into four families: use, experience, delivery and outcome. Acceptance rate and share of generated lines reflect how a tool feels and is configured, and Goodhart's law applies when they become targets. The J-curve leaves the programme with an investment ledger and a return ledger. The studies disagree on the surface and agree underneath: the effect depends on the task, the person, the codebase and the vintage of the tool, perceived and measured effects can diverge, and throughput and stability are read together. What an organisation can influence is the quality of its own evidence.
An internal experiment needs a comparison, a period matched to the outcome, primary data, an independent oracle and a plan for the result, and the programme a stop rule with a stop path outside the tool and the sponsor. The record AVR-* keeps the quoted and the measured figure side by side and carries an evidence age. Chapter 21 turns from the measure to the people measured: how review culture, trust and the safety to speak up decide whether any of these figures can be believed.
Sources
- Nordqvist, G. (2026). AI Governance: Governing Artificial Intelligence in European Enterprises and Public Authorities. The Architecture as Code Series, Book 2, published at aig.geon.se. (162, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Boss: When Artificial Intelligence Manages People in European Enterprises and Public Authorities. The Architecture as Code Series, Book 7, published at aiboss.geon.se. (167, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Purple: How Red and Blue Learn Together When AI Joins the Loop in European Enterprises and Public Authorities. The Architecture as Code Series, Book 9, published at aipurple.geon.se. (169, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Operations: How Artificial Intelligence Transforms IT Operations in European Enterprises and Public Authorities. The Architecture as Code Series, Book 10, published at aiops.geon.se. (170, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Leader: How Leadership Roles Change When AI Is Used Broadly in European Enterprises and Public Authorities. The Architecture as Code Series, Book 11, published at leader.geon.se. (174, Nordqvist, 2026)
- Manheim, D. & Garrabrant, S. (2019). Categorizing Variants of Goodhart's Law. arXiv:1803.04585, first submitted 13 March 2018, version 4 of 24 February 2019. (61, Manheim & Garrabrant, 2019)
- Forsgren, N., Storey, M.-A., Maddila, C., Zimmermann, T., Houck, B. & Butler, J. (2021). The SPACE of Developer Productivity: There's more to it than you think. ACM Queue 19(1), 20-48. (62, Forsgren et al., 2021)
- Becker, J., Rush, N., Barnes, E. & Rein, D. (2025). Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity. arXiv:2507.09089, submitted 12 July 2025, revised 25 July 2025. (63, Becker et al., 2025)
- Brynjolfsson, E., Rock, D. & Syverson, C. (2021). The Productivity J-Curve: How Intangibles Complement General Purpose Technologies. American Economic Journal: Macroeconomics 13(1), 333-372. (52, Brynjolfsson et al., 2021)
- Humlum, A. & Vestergaard, E. (2025). Still Waters, Rapid Currents: Early Labor Market Transformation under Generative AI. NBER Working Paper 33777, May 2025, revised March 2026. (53, Humlum & Vestergaard, 2025)
- Brynjolfsson, E., Li, D. & Raymond, L. R. (2025). Generative AI at Work. The Quarterly Journal of Economics 140(2), 889-942. (68, Brynjolfsson et al., 2025)
- Dell'Acqua, F., McFowland III, E., Mollick, E., Lifshitz-Assaf, H., Kellogg, K. C., Rajendran, S., Krayer, L., Candelon, F. & Lakhani, K. R. (2023). Navigating the Jagged Technological Frontier: Field Experimental Evidence of the Effects of AI on Knowledge Worker Productivity and Quality. Harvard Business School Working Paper 24-013; SSRN 4573321. (81, Dell'Acqua et al., 2023)
- Cui, Z. (K.), Demirer, M., Jaffe, S., Musolff, L., Peng, S. & Salz, T. (2024). The Effects of Generative AI on High-Skilled Work: Evidence from Three Field Experiments with Software Developers. SSRN 4945566; later published in Management Science (DOI: 10.1287/mnsc.2025.00535). (176, Cui et al., 2024)
- Peng, S., Kalliamvakou, E., Cihon, P. & Demirer, M. (2023). The Impact of AI on Developer Productivity: Evidence from GitHub Copilot. arXiv:2302.06590, submitted 13 February 2023. (175, Peng et al., 2023)
- Harvey, N. & DeBellis, D. (2025). Announcing the 2025 DORA report: State of AI-assisted Software Development. Google Cloud Blog, 23 September 2025. (42, Harvey & DeBellis, 2025)
- Harvey, N. & DeBellis, D. (2024). Highlights from the 10th DORA report (page title: Announcing the 2024 DORA report). Google Cloud Blog, 22 October 2024. (221, Google Cloud, 2024)
- DevOps Research and Assessment (DORA). DORA metrics guide. dora.dev/guides/dora-metrics. (222, Harvey, 2026)
- Noda, A., Storey, M.-A., Forsgren, N. & Greiler, M. (2023). DevEx: What Actually Drives Productivity. ACM Queue, 2023. (227, Noda et al., 2023)
- Ziegler, A., Kalliamvakou, E., Simister, S., Sittampalam, G., Li, A., Rice, A., Rifkin, D. & Aftandilian, E. (2022). Productivity Assessment of Neural Code Completion. arXiv:2205.06537, submitted 13 May 2022; MAPS '22. (210, Ziegler et al., 2022)
- Paradis, E., Grey, K., Madison, Q., Nam, D., Macvean, A., Meimand, V., Zhang, N., Ferrari-Church, B. & Chandra, S. (2024). How much does AI impact development speed? An enterprise-based randomized controlled trial. arXiv:2410.12944, submitted 16 October 2024. (185, Paradis et al., 2024)
- METR (2026). We are Changing our Developer Productivity Experiment Design. METR blog, 24 February 2026. (186, METR, 2026)
- Stack Overflow (2025). 2025 Stack Overflow Developer Survey. (217, Stack Overflow, 2025)
- Pichai, S. (2024). Q3 earnings call: CEO's remarks. Google, 29 October 2024. (45, Pichai, 2024)
- European Parliament and Council of the European Union. Regulation (EU) 2022/2554 on digital operational resilience for the financial sector (DORA). Official Journal of the European Union, 27 December 2022. (2, European Union, 2022)
- Federal Republic of Germany. Betriebsverfassungsgesetz (BetrVG), section 87 (Mitbestimmungsrechte). gesetze-im-internet.de. (9, Germany, n.d.)
- Swedish Parliament (Sveriges riksdag). Lag (1976:580) om medbestämmande i arbetslivet, sections 10 to 12. Svensk författningssamling 1976:580. (10, Swedish Parliament (Sveriges riksdag), 1976)